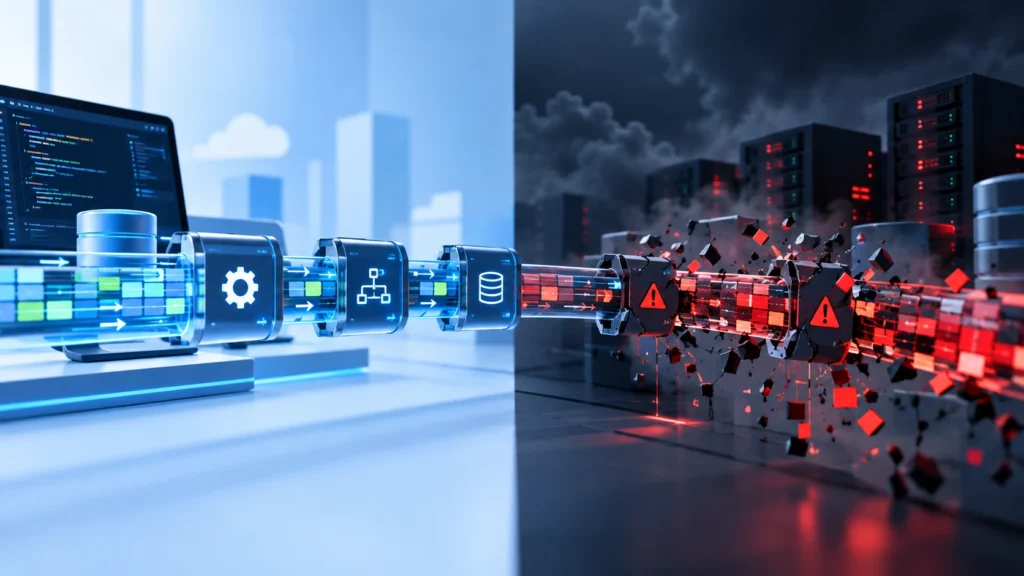
Data pipelines fail in production because production removes the assumptions that make development predictable. Real systems introduce larger and skewed datasets, messy records, schema changes, late-arriving data, retries, concurrent workloads, and restricted permissions. Production-ready pipelines address these gaps with data validation, schema contracts, idempotent writes, recovery strategies, and data-level observability.
Executive Summary
A data pipeline can pass every development test and still fail in production—not because the architecture is necessarily wrong, but because development often removes the conditions that make production difficult: real data volume, uneven distributions, malformed records, schema changes, late-arriving data, concurrent jobs, retries, and production permissions.
The result is often more dangerous than a failed job.
The pipeline may complete successfully while:
- dropping records
- creating duplicates
- producing stale data
- silently converting invalid values
- missing late-arriving events
- overwriting newer records with older ones
- feeding incorrect numbers to downstream dashboards
AWS identifies increasing data volume, source-structure changes, poor data quality, duplicate data, source timeliness, and limited testing interfaces among the recurring challenges in production data pipelines.
The central lesson is:
A pipeline is not production-ready because it works once on clean development data. It is production-ready when it continues to produce trustworthy data when the input is messy, the workload is large, jobs overlap, the source changes, and execution is interrupted and retried.
TL;DR
A data pipeline fails in production when the assumptions validated in development no longer hold under real operating conditions.
Development often removes six things at once:
- Data scale and uneven distributions
- Messy real-world data
- Schema changes
- Late-arriving and out-of-order data
- Retries, duplicate processing, and concurrent execution
- Production permissions, configurations, and resource constraints
The most important production-readiness practices are:
- Test the distribution of values, not only row counts.
- Include malformed and unexpected records in test data.
- Treat schema as a contract and explicitly validate required columns.
- Design incremental processing around event time where appropriate.
- Make writes genuinely idempotent.
- Deduplicate within each batch before a
MERGE.- Prevent stale records from overwriting newer state.
- Quarantine bad records rather than silently dropping them.
- Monitor the data, not just the pipeline job.
- Test failure deliberately by killing, retrying, duplicating, and replaying workloads.
Most importantly:
A green pipeline is evidence that the job completed. It is not proof that the data is correct.
Why Data Pipelines Work in Development but Fail in Production
Data pipelines often work in development because development environments use smaller, cleaner, more predictable datasets and simpler execution conditions. Production introduces larger and uneven workloads, malformed data, upstream schema changes, late events, retries, concurrency, and different permissions. These conditions expose assumptions that development never tested.
When an engineer says:
“The pipeline works.”
they may actually mean:
“Given one clean, complete, fixed dataset, run once, by one process, with full permissions, on an idle machine, and the output looks correct.”
Production asks a different question:
“Does the pipeline still produce correct data when everything around it behaves like a real system?”
Production data keeps moving.
Other jobs run simultaneously.
Sources change.
Records arrive late.
Schedulers retry.
Service accounts have restricted permissions.
Compute resources are shared.
Failures can happen halfway through a write.
Current production-pipeline guidance reflects this broader lifecycle: ingestion, transformation, operationalization, production monitoring, backfills, security, and scaling all introduce separate design concerns.
Databricks’ current pipeline guidance explicitly covers ingestion, transformation, operationalization, production monitoring, retries, idempotency, late-arriving data, service identities, backfills, and data-quality expectations.
That is the gap this article addresses.
Read our blog on Essential Design Patterns in Modern Data Pipelines
The 6 Gaps Between Development and Production
Gap Development Assumption Production Reality Typical Failure Data scale Small, balanced sample Large and skewed Timeouts, memory pressure Data quality Clean records Nulls, malformed values, duplicates Silent wrong results Schema Stable structure Upstream changes Missing or mis-mapped fields Time Data arrives in order Late/out-of-order records Missing or misplaced data Execution Runs once Retries, replays, concurrency Duplicates, stale updates Environment Full access, idle resources Service accounts, limits, contention Permission and runtime failures These gaps are not unusual edge cases. They are recurring characteristics of production data systems. Research on data-pipeline quality also identifies data types, integration, testing scope, data drift, and differences between development and production data as important contributors to pipeline reliability.
1. Data Size and Uneven Data Distributions
A development dataset can validate pipeline logic while completely hiding production-scale problems. The critical difference is not only the number of rows but also how those rows are distributed across keys, partitions, files, and values. Skewed joins, high-cardinality operations, memory-intensive transformations, and excessive small files can turn a fast development run into a production timeout.
Development often uses:
SELECT *
FROM orders
LIMIT 100000;
or:
WHERE order_date = CURRENT_DATE - INTERVAL '1 day'That proves the transformation works on a subset.
It does not prove the transformation scales.
Data skew
Suppose development contains:
Customer A → 100 orders
Customer B → 110 orders
Customer C → 90 orders
...
Production may contain:
Customer A → 40% of all orders
Everyone else → 60%
A distributed join can now behave very differently.
One partition may receive a disproportionate amount of the data, creating:
- long-running tasks
- memory pressure
- shuffle overhead
- executor imbalance
- timeouts
The pipeline did not become logically wrong.
The distribution changed.
Memory Pressure
Operations such as:
df.collect()or:
df.toPandas()can appear harmless on a development dataset and become dangerous when the result is hundreds of millions of rows.
The reason is simple:
Distributed data is being pulled toward a single machine or driver process.
A pipeline should therefore be tested against the largest realistic intermediate result, not merely the largest input file.
Small Files
A pipeline that writes a small batch every few minutes can eventually create thousands or millions of small files.
The failure may not be:
“Pipeline crashed.”
It may be:
“Dashboard query now takes 15 minutes.”
This is a production performance problem that can remain invisible during development because the development dataset does not have enough files or history to expose it.
The Production Test
Do not test only:
How many rows can the pipeline process?
Also test:
- How are rows distributed?
- What is the largest partition?
- How many distinct keys exist?
- What is the largest intermediate dataset?
- How many files are created?
- How does runtime change as history grows?
Key lesson
2. Messy Real-World Data
Production data contains values that development datasets frequently remove: nulls, blank strings, malformed numbers, inconsistent dates, encoding problems, duplicate identifiers, and unexpected formats. The most dangerous cases are those that are accepted by the pipeline and converted into plausible but incorrect results rather than producing an explicit failure.
Development data is often:
the data that already loaded successfully.
Production contains everything else.
Examples include:
- unexpected nulls
- empty strings
"N/A"in numeric fields- malformed dates
- multiple date formats
- character-encoding problems
- commas inside unquoted CSV fields
- duplicate business keys
- records representing deletions
- invalid identifiers
The dangerous case is not necessarily a crash.
It is:
Bad input
   ↓
Accepted
   ↓
Converted
   ↓
Wrong value
   ↓
Pipeline succeeds
Silent Conversion Is Worse Than a Loud Failure
Consider a numeric field arriving as:
1,299.00when the pipeline expects a plain numeric representation.
Depending on the Spark version, SQL expression, parsing method, and ANSI configuration, malformed casts may either raise an exception or produce a null-like result. Spark’s documentation explicitly distinguishes ANSI behavior, where invalid operations can throw, from tolerant conversion functions such as
try_cast, which intentionally returnNULL.That makes configuration and parsing behavior part of the pipeline’s correctness contract.
For example, with ANSI behavior enabled:
invalid conversion
       ↓
exception
       ↓
pipeline stops
       ↓
engineer investigates
With tolerant conversion:
invalid conversion
       ↓
NULL
       ↓
pipeline continues
       ↓
aggregate may be wrong
Neither behavior is universally correct.
The important point is:
Know which behavior your production pipeline actually uses.
Quarantine Instead of Silent Loss
For data-quality failures, a useful pattern is:
                    Input
                      ↓
               Validation Layer
                 /          \
                ↓            ↓
             Valid        Invalid
                ↓            ↓
          Clean Layer     Quarantine
                             ↓
                       Reject Reason
A quarantined record should retain enough information to answer:
- What failed?
- Why did it fail?
- When did it arrive?
- Which source produced it?
- Which pipeline run processed it?
This allows the pipeline to continue processing valid records without hiding bad data.
Modern managed pipeline guidance increasingly uses expectations, rescued-data patterns, or dead-letter outputs for exactly this purpose.
3. Schema Changes and What Your Read Configuration Actually Does
Schema drift occurs when an upstream source adds, removes, renames, or changes fields or data types. A reader configuration alone is not always enough to turn a schema change into a clear failure. The safest production approach is to define the expected schema explicitly and validate required fields before transformation or business logic runs.
Imagine the source changes:
customer_idto:
cust_idThe pipeline still executes.
But downstream logic expects:
customer_idNow the question becomes:
Does the reader fail, adapt, or silently produce missing values?
The answer depends on:
- file format
- reader
- schema configuration
- schema-evolution settings
- processing engine
- write target
Modern platforms provide multiple schema-drift strategies, including strict failure, rescue/quarantine behavior, and controlled schema evolution. Microsoft and Databricks both document these as explicit architectural choices rather than something pipelines should leave to chance.
Why Fixed Schema Alone Is Not a Complete Contract
A fixed schema is useful.
But a fixed schema should not be treated as the only protection against a renamed field.
A missing field can behave differently from an unreadable record depending on the reader and format.
That means this:
“We use a fixed schema, so schema changes will fail.”
may not be a sufficient production guarantee.
A better approach is to explicitly validate required fields.
EXPECTED = {
    "order_id",
    "customer_id",
    "order_amount",
    "currency_code",
    "ordered_at"
}

missing = EXPECTED - set(df.columns)

if missing:
    raise SchemaContractError(
        f"Expected columns are missing from the source: {sorted(missing)}"
    )
That converts a potentially silent structural change into an explicit contract failure.
Why this matters
Without the check:
Upstream rename
      ↓
Pipeline succeeds
      ↓
Missing field
      ↓
NULLs / incomplete transformation
      ↓
Wrong dashboard
With the check:
Upstream rename
      ↓
Schema contract fails
      ↓
Pipeline stops
      ↓
Engineer investigates
Production principle
Schema evolution should be an explicit policy, not an accidental behavior.
4. Late-Arriving and Out-of-Order Data
Late-arriving data is a time-model problem as much as an incremental-loading problem. If a pipeline uses arrival time when business logic depends on event time, records that arrive late can be assigned to the wrong period or skipped entirely. A documented lookback window, event-time logic, and safe reprocessing strategy can reduce this risk.
Many incremental pipelines begin with:
“Load everything since the last run.”
That works when records arrive in order.
Production rarely guarantees that.
There are two common failure modes.
Arrival Time vs. Event Time
Suppose:
Order placed: Tuesday
Order arrives: Friday
If the pipeline filters on arrival time:
Fridaybut reporting uses event time:
Tuesdaythe record may be assigned incorrectly—or missed by a simple incremental filter.
High-Water Marks Can Miss Corrections
Suppose the pipeline remembers:
last_updated_at = Friday 10:00A source system later corrects a record whose timestamp is:
Thursday 16:00This filter:
df = source.filter(
    F.col("updated_at") > last
)
will never see the correction.
A Lookback Window
Instead, deliberately reload a fixed window:
watermark = load_watermark("orders")

lookback = watermark - timedelta(hours=48)

df = source.filter(
    F.col("updated_at") >= lookback
)
The exact window is a business decision.
Ask:
How late can valid data arrive?
If the answer is 48 hours, document that assumption and test it.
For streaming workloads, event-time watermarks are one established way to bound how long systems wait for late data; modern pipeline guidance also treats late and out-of-order data as an explicit design consideration.
But a Lookback Creates Another Requirement
If you reload 48 hours of data every run, the write must be safe to repeat.
Otherwise:
Reload 48 hours
       ↓
Append
       ↓
Duplicate records
So:
Late-data handling and idempotent writes are connected design problems.
5. Retries, Replays and Jobs Running Together
Production pipelines should assume that processing can happen more than once. Schedulers retry failed tasks, event systems may deliver messages more than once, and engineers may manually rerun failed jobs. A production-safe write therefore needs explicit idempotency and duplicate-handling behavior rather than assuming every batch executes exactly once.
Production execution is not:
Run once
 ↓
Success
It is more like:
Run
 ↓
Partial failure
 ↓
Retry
 ↓
Replay
 ↓
Manual rerun
Databricks explicitly defines idempotency as producing the same result when the same input is processed multiple times and recommends idempotent handling at system boundaries where processing may be at-least-once.
AWS similarly identifies idempotency as an important technique for reliable ETL pipelines.
Why Append Can Create Duplicates
Suppose:
1. Write 60% of batch
2. Job fails
3. Scheduler retries
4. Entire batch runs again
With an append:
60% already exists
       +
100% retry
       =
160% of intended data
The pipeline may report success on the retry.
The table is now wrong.
Is MERGE Enough to Make a Pipeline Idempotent?
No. A
MERGEis useful for idempotent upserts, but the merge condition alone does not guarantee correct repeatability. The source batch must also be deterministic and deduplicated, and older records should not overwrite newer target state when late-arriving data is possible.This is one of the most important production details in the original article.
Consider:
MERGE INTO silver.orders AS target
USING (
    SELECT *
    FROM (
        SELECT *,
               ROW_NUMBER() OVER (
                   PARTITION BY order_id
                   ORDER BY source_updated_at DESC, event_id DESC
               ) AS rn
        FROM staging.orders_incremental
    )
    WHERE rn = 1
) AS source

ON target.order_id = source.order_id

WHEN MATCHED
     AND source.source_updated_at > target.source_updated_at
THEN UPDATE SET *

WHEN NOT MATCHED
THEN INSERT *;
Two controls matter.
Delta Lake documents that a merge can fail when multiple source rows match the same target row and recommends preprocessing the source to eliminate multiple matches.
Control 1: Deduplicate Within the Batch
A single batch can contain:
order_id = 1001
order_id = 1001
because of:
- producer retries
- source corrections
- replayed windows
- duplicate events
Delta Lake documents that a
MERGEcan fail when multiple source rows match the same target row because the update becomes ambiguous. Its documented solution is to preprocess the source and retain the appropriate record—for example, the latest change per key.That is what the
ROW_NUMBER()step accomplishes.The tie-breaker matters too:
ORDER BY source_updated_at DESC,
         event_id DESC
Without a deterministic tie-breaker, two records with the same timestamp may not have a stable winner.
Control 2: Reject Stale Updates
Suppose the target contains:
order_id = 1001
amount = 150
updated_at = Friday
A late source record arrives:
order_id = 1001
amount = 120
updated_at = Thursday
Without:
source.source_updated_at > target.source_updated_atthe older record can overwrite newer state.
The result is not a duplicate.
It is data regression.
Important Terminology
A pipeline is genuinely idempotent when repeating the same logical input produces the same resulting state.
That is stronger than:
“We use MERGE.”
Production principle
Idempotency is a property of the complete write path—not the name of one SQL statement.
6. Different Permissions, Configuration and Runtime Conditions
A pipeline can work in development because developers typically run with broader permissions, local credentials, different configuration values, more available compute, and fewer competing workloads. Production runs under service identities, secret stores, network restrictions, resource limits, and concurrent workloads that must be tested explicitly.
Common differences include:
Identity
Development:
Developer account
↓
Broad permissions
Production:
Service account
↓
Scoped permissions
The pipeline may suddenly be unable to:
- write to a location
- read a source
- access a secret
- update a table
- invoke an external service
Secrets
Development:
local.envProduction:
secret manager / key vaultThe variable name may differ.
The secret may have different scope.
The credential may have expired.
Runtime Configuration
Development:
- generous timeout
- low concurrency
- local resources
- minimal data
- no competing workloads
Production:
- stricter timeout
- shared compute
- concurrency
- resource quotas
- larger data
- network controls
Service Identity Testing
One of the simplest production-readiness tests is:
Run the pipeline in a production-like environment using the same identity and configuration constraints it will have in production.
Current production pipeline guidance similarly recommends dedicated service identities, secret management, version-controlled deployment, and environment parameterization rather than personal credentials and hard-coded configuration.
The Missing Layer: A Pipeline Can Succeed While the Data Is Wrong
The six gaps above explain why production exposes problems.
There is another question:
How will you know when the pipeline produces the wrong result without throwing an error?
This is where data observability and data-quality monitoring become essential.
A job monitor can tell you:
Job status: SUCCESSIt cannot necessarily tell you:
Revenue: 23% below expectedor:
Rows: 41% below normalor:
Required column missingor:
Data is now 72 hours staleWhat to Monitor Beyond Pipeline Status
Production data pipelines need data-level monitoring in addition to job-level monitoring. Useful signals include freshness, volume, schema, and reconciliation checks because a pipeline can complete successfully while producing stale, incomplete, structurally changed, or incorrect data.
Four checks catch a large portion of the silent failures described in this article.
1. Freshness
Ask:
How long since this table successfully received expected data?
Example:
Expected: < 2 hours
Actual:   17 hours
Status:   ALERT
2. Volume
Compare the current row count against a relevant baseline.
For example:
Today:      8,000,000 rows
Expected:   7,500,000–8,500,000
versus:
Today:      80 rows
Expected:   8,000,000
The second case should be highly visible.
3. Schema
Check:
- required columns
- unexpected columns
- data types
- schema fingerprint
- nullable/non-nullable expectations
4. Reconciliation
Compare pipeline outputs against an authoritative source where possible.
For example:
Source order count
        vs.
Target order count
or:
Source revenue
        vs.
Warehouse revenue
The goal is not to guarantee perfect equality in every architecture.
The goal is to make unexplained divergence visible.
Modern production pipeline guidance explicitly treats data-quality metrics, row counts, backlog, event logs, and failure notifications as part of production operation rather than optional extras.
Read our blog on Serverless Data Pipelines: Simplifying Data Infrastructure for Scalable, Intelligent Systems
Production-Safe Pipeline Architecture
A production-safe data pipeline separates immutable landing data, validation and quarantine, clean transformation layers, and business-facing outputs while adding monitoring across freshness, volume, schema, and reconciliation. The design should also allow downstream processing to be rerun without corrupting previously processed data.
A practical architecture is:
                    SOURCE SYSTEMS
                         │
                         ▼
                ┌─────────────────┐
                │  LANDING / RAW  │
                │ Immutable Input  │
                └────────┬────────┘
                         │
                         ▼
                ┌─────────────────┐
                │ VALIDATION      │
                │ Schema          │
                │ Quality         │
                │ Type Checks     │
                └───────┬─────────┘
                    ┌───┴───┐
                    ▼       ▼
                 VALID    INVALID
                    │       │
                    ▼       ▼
                 CLEAN   QUARANTINE
                    │
                    ▼
              BUSINESS LAYER
                    │
                    ▼
             REPORTING / ML /
             APPLICATIONS
Across every stage:
Freshness
Volume
Schema
Quality
Reconciliation
Lineage
Run Status
Two Rules Carry Most of the Weight
Rule 1: Never Change the Landing Data
Keep raw input exactly as it arrived.
Why?
Because if a transformation bug appears three weeks later, you want to be able to say:
“Reprocess the original data.”
rather than:
“Ask the source system to send us three weeks of history again.”
Immutable landing data provides a recovery boundary.
Rule 2: Every Downstream Step Should Be Re-Runnable
This is more difficult than it sounds.
A re-runnable step requires:
- deterministic transformations
- stable keys
- controlled deduplication
- safe writes
- appropriate state tracking
- explicit handling of late data
Current Databricks guidance similarly treats idempotency and recovery as explicit pipeline design concerns, especially at system boundaries where at-least-once processing is possible.
Handling Partial Failure: 12 Bad Rows Out of 8 Million
A robust pipeline should distinguish between isolated bad records and systemic data-quality failures. Rather than failing the entire workload or silently dropping invalid rows, quarantine rejected records, record the reason, and use a reject-rate threshold to determine when the pipeline should stop or escalate.
Suppose:
Total rows:     8,000,000
Rejected rows:         12
That may be normal noise.
Now consider:
Total rows:            80
Rejected rows:         12
That is a serious upstream change.
This is why a percentage is often more informative than a fixed count.
df.cache()

valid = df.filter(quality_predicate)

invalid = (
    df.filter(~quality_predicate)
      .withColumn("reject_reason", reason_expr)
)

total = df.count()
rejected = invalid.count()

invalid.write.mode("append").saveAsTable(
    "quarantine.orders"
)

reject_rate = rejected / max(total, 1)

if reject_rate > 0.01:
    raise DataQualityError(
        f"Reject rate {reject_rate:.2%} is above the limit"
    )
The threshold should be defined by the business context.
A regulatory pipeline may tolerate almost no rejected records.
An exploratory analytics pipeline may tolerate more.
The principle
Do not choose between “fail everything” and “ignore everything.” Define the threshold that determines what happens.
Example: An Order Pipeline Before and After Production Hardening
Consider an order pipeline that receives events every 15 minutes and feeds a revenue dashboard. The development version may simply read new files, transform columns, append records, and aggregate revenue. Production hardening adds schema contracts, quarantine, deduplication, stale-update protection, documented lookback windows, and data-level monitoring.
Development Version
New Files
   ↓
Read
   ↓
Transform
   ↓
Append
   ↓
Daily Revenue
Tested on:
- one day
- clean data
- stable schema
- no retries
- one process
Row counts match.
Pipeline succeeds.
What Production Introduces
Production Condition Failure Storage timeout + retry Duplicate orders Upstream field change Missing or null values Late returns Wrong reporting date Malformed amount Incorrect revenue Large customer skew Long-running job Restricted service account Permission failure The important distinction is that some failures are loud while others are silent.
Loud
Permission deniedEngineering sees it.
Silent
Currency field becomes NULLFinance sees the impact later.
The Hardened Version
The production design adds:
Source
  ↓
Immutable Landing
  ↓
Schema Contract
  ↓
Data Quality Validation
  ├── Valid → Clean Layer
  └── Invalid → Quarantine
  ↓
Deduplicate Batch
  ↓
Apply Lookback
  ↓
Idempotent Merge
  ↓
Business Aggregation
  ↓
Freshness / Volume / Schema / Reconciliation Checks
  ↓
Dashboard
The code did not necessarily become dramatically more complex.
The guarantees became stronger.
Test Data: The Production Gap You Can Actually Close
Realistic test data is one of the most practical ways to reduce the development-to-production gap. The most useful test datasets preserve realistic value distributions and deliberately include edge cases such as nulls, duplicate keys, malformed numbers, late records, schema changes, and encoding problems.
There are two useful approaches.
Factor Masked Production Copy Realistic Sample + Edge Cases Real-world distribution Excellent Can be strong if designed well Scale testing Excellent Limited Cost High Low–medium Compliance work Significant Lower Edge cases Existing cases Can be deliberately expanded Correctness testing Strong Strong Maintenance High Moderate Best use Performance/scale validation Automated correctness testing You do not necessarily need a full production copy for every test.
A well-designed test dataset can include:
- empty values
- nulls
- duplicate keys
- malformed numeric values
- multiple date formats
- late records
- out-of-order records
- renamed columns
- missing columns
- unusually large groups
- encoding problems
The key is to preserve distribution, not simply row count.
How to Test Data Pipelines for Production Failures
The fastest way to find production-readiness gaps is to deliberately reproduce production failure conditions in a safe test environment. Kill jobs mid-write, replay the same batch, introduce schema changes, inject late records, duplicate keys, and run under the production service identity. Each failure should become a repeatable test.
Every major failure mode in this article can be tested deliberately.
Test 1: Kill and Retry
- Start the pipeline.
- Interrupt it during the write.
- Run it again.
- Compare row counts and business keys.
Question:
Did the retry create duplicates?
Test 2: Replay the Same File
Load the same source file twice.
Question:
Does the target state remain correct?
Test 3: Rename a Required Column
Change:
customer_idto:
cust_idQuestion:
Does the pipeline fail clearly, or does the data continue with missing values?
Test 4: Send an Older Record
Load:
updated_at = yesterdayafter:
updated_at = todayQuestion:
Can stale data overwrite newer state?
Test 5: Duplicate a Business Key
Put the same key into one batch twice.
Question:
Does the pipeline deterministically select the correct record or fail safely?
Test 6: Run as the Production Identity
Use the same:
- service account
- permissions
- secret mechanism
- network path
- configuration
Question:
Does it still work?
Test 7: Introduce Data Skew
Create one key representing a very large share of records.
Question:
Does one task become the bottleneck?
Production Readiness Checklist for Data Pipelines
Before promoting a pipeline to production, ask:
Data Scale
- Have we tested realistic data volume?
- Have we tested skew?
- Have we tested high-cardinality operations?
- Have we checked file counts and partition sizes?
Data Quality
- Have we tested nulls?
- Have we tested malformed values?
- Have we tested duplicate keys?
- Are invalid records quarantined?
- Are reject thresholds defined?
Schema
- Is the expected schema documented?
- Are required columns explicitly checked?
- Is schema evolution intentional?
- Are type changes detected?
Time
- Do we distinguish event time from arrival time?
- Have we tested late data?
- Have we tested out-of-order data?
- Is the lookback window documented?
Writes
- What happens if the job runs twice?
- Is the write idempotent?
- Are duplicate keys removed within each batch?
- Can stale records overwrite newer records?
Environment
- Does the production service account work?
- Are production secrets tested?
- Are production timeouts tested?
- Are concurrency limits understood?
Observability
- Do we monitor freshness?
- Do we monitor row volume?
- Do we detect schema changes?
- Do we reconcile critical totals?
- Do alerts fire before business users report problems?
What Changes When These Gaps Close?
Change Result Retries become safe Duplicate-data incidents decrease Schema contracts are explicit Structural changes become visible Raw data is immutable Recovery becomes reprocessing Bad records are quarantined Good data can continue flowing Late data uses controlled lookback Corrections can be incorporated Merge handles duplicates and staleness Replays are safer Production identity is tested Permission surprises move left Data-level monitoring exists Silent failures become detectable The objective is not to eliminate every possible failure.
It is to move failures from:
unexpected + silent + expensive
to:
deliberate + detectable + recoverable.
Where Production Hardening Is Not Worth the Cost
Not every data pipeline needs the same level of production hardening. The right investment depends on business impact, data criticality, recovery cost, volume, and operational exposure. A low-value internal experiment may not justify complex idempotency and reconciliation controls, while regulatory, financial, customer, or machine-learning pipelines usually require stronger guarantees.
Complexity has a cost.
Consider:
MERGE vs. Append
A merge may cost more compute than an append.
For enormous, low-value datasets, the cost may outweigh the benefit.
Stable Keys
Some legacy systems do not provide stable business keys.
In such cases, deterministic hashes may help—but only when the fields used to create the hash are themselves stable.
Clock Reliability
Staleness checks based on:
source_updated_atassume that the producer’s timestamps are meaningful and sufficiently trustworthy.
Clock inconsistencies can undermine the comparison.
External Side Effects
A storage pattern cannot undo:
- an email
- a payment
- a notification
- an API request
External systems need their own idempotency mechanisms or deduplication controls.
The principle
Match reliability engineering effort to the cost of being wrong.
A pipeline powering a regulatory report and one powering an internal experiment should not necessarily receive identical architecture.
Six Questions to Ask About Your Data Pipelines
These questions turn the article into a practical production-readiness review.
1. What happens if this write runs twice?
Find every:
- append
- delete-then-insert
- merge
- external write
Then test it.
2. Does the merge deduplicate the batch and reject stale updates?
If either is missing, ask whether the pipeline is genuinely safe to rerun.
3. Which clock does the incremental filter use?
Is it:
- event time?
- arrival time?
- source update time?
Does that match the business definition of the data?
4. What happens when a required column disappears?
Do not answer from memory.
Run the actual production reader configuration.
Then determine whether:
- the pipeline fails
- the field becomes null
- the field is rescued
- the schema evolves
- the data continues incorrectly
5. Does the test dataset preserve value distribution?
A dataset with:
1,000,000 rowscan still be unrealistic if production has:
one key = 40% of the data6. Would you know if the pipeline became wrong?
For each failure mode, identify:
Which alert would fire?
If the answer is:
“Someone will notice in the dashboard.”
you have a monitoring gap.
Common Data Pipeline Production Failure Modes
Failure Mode Why Development Misses It Production Control Data skew Sample is too balanced Distribution-aware testing Memory pressure Dataset is too small Scale testing Small files History is too short File/partition monitoring Invalid values Test data is clean Edge-case data + validation Schema drift Source is stable Schema contracts Late data Sample arrives in order Event-time + lookback Duplicate processing Job runs once Idempotent writes Stale updates Data arrives in order Sequence/timestamp checks Permission failure Developer has broad access Production identity testing Silent corruption Job returns success Data observability Development vs. Production: The Real Difference
The most important difference is not:
Dev has less data.
It is:
Dev removes uncertainty.
Development often has:
Clean
Small
Stable
Predictable
Single-user
Full-access
One-time execution
Production has:
Messy
Large
Changing
Concurrent
Restricted
Retrying
Late
Partial
Uncertain
That is why:
Production is not simply a larger development environment.
It is a different operating condition.
The Production Failure Loop
A reliable engineering organization turns each production failure into a reusable test.
Production Failure
       ↓
Root Cause
       ↓
Failure Scenario
       ↓
Automated Test
       ↓
Pipeline Guardrail
       ↓
Monitoring Rule
       ↓
Future Prevention
For example:
Duplicate revenue
       ↓
Retry after partial write
       ↓
Replay test
       ↓
Idempotent merge
       ↓
Duplicate-key check
       ↓
Volume/reconciliation alert
This is how reliability improves over time.
The Core Principle: Design for Failure, Not Just the Happy Path
A pipeline that works on clean development data has demonstrated that its transformation logic can work.
It has not demonstrated that it can survive production.
Production readiness means testing what development normally removes:
- realistic scale
- uneven distributions
- malformed data
- schema changes
- late events
- duplicate processing
- partial execution
- restricted permissions
- concurrent workloads
- changing dependencies
The most valuable test may be surprisingly simple:
Kill the pipeline halfway through a write. Then run it again.
If the resulting table is wrong, you have learned something important before production learns it for you.
Conclusion
Picking the right design is necessary, and it is not enough. A pipeline built on good patterns still fails the first time it meets production, because the environment that tested it — small, clean, fixed, one job at a time, full permissions — is not the environment it has to survive.
The gaps are specific and there are not many of them: the spread of values rather than the row count, test data that only contains what already worked, a read mode that fails quietly, a filter using the wrong clock, a merge that is not quite safe to repeat, and permissions nobody tried. None of these need a different design. All of them need somebody to ask what happens when the step runs twice.
The next step takes an afternoon. Take the pipeline whose failure would hurt most, kill it mid-write in a test environment, run it again, and count the rows. What you find will tell you how much of the rest of this article applies to you.
Key Takeaways
- A data pipeline can be logically correct and still fail under production conditions.
- Production introduces scale, skew, messy data, schema changes, late records, retries, concurrency, and restricted permissions.
- Data distribution matters as much as data volume when testing pipeline scalability.
- Silent data-quality failures are often more dangerous than visible job failures.
- Schema evolution should be an explicit policy, not an accidental reader behavior.
- Fixed schemas are useful, but explicit required-column validation provides a stronger contract.
- Late-arriving data requires careful handling of event time, watermarks or lookback windows, and safe reprocessing.
- A
MERGEalone does not guarantee idempotency.- Batch deduplication and stale-update protection are important for repeatable incremental writes.
- Data observability must complement job monitoring.
- Immutable landing data makes recovery and reprocessing easier.
- The best production tests deliberately reproduce failure conditions before deployment.
FAQs
1. Why do data pipelines fail in production but not development?
Data pipelines often fail in production because development uses smaller, cleaner, more predictable data and simpler execution conditions. Production introduces larger and skewed datasets, malformed records, schema changes, late data, retries, concurrent jobs, restricted permissions, and resource constraints.
2. What are the most common data pipeline production failures?
Common failures include data skew, memory pressure, malformed input, schema drift, missing fields, late-arriving data, duplicate processing, stale updates, permission problems, resource contention, and silent data-quality degradation.
3. How do you make a data pipeline production-ready?
Test realistic scale and data distributions, validate incoming data, enforce schema contracts, handle late-arriving records, make writes idempotent, test retries, use production-like permissions, preserve raw input, and monitor freshness, volume, schema, quality, and reconciliation.
4. Is MERGE enough to make a data pipeline idempotent?
No. A MERGE can support idempotent upserts, but the source batch may still contain duplicate keys, and stale records can overwrite newer state unless the merge includes appropriate deduplication and ordering or staleness conditions. Delta Lake documents that multiple source rows matching the same target row can cause a merge failure.
5. Should a data pipeline fail when it encounters bad records?
Not necessarily. A better approach is often to quarantine invalid records with explicit rejection reasons and use a business-defined reject-rate threshold to determine whether the pipeline should continue, warn, or fail.
6. How do you detect silent data pipeline failures?
Monitor data-level signals such as freshness, row volume, schema, null rates, distribution changes, duplicate rates, and reconciliation against authoritative sources. Job status alone cannot detect every form of data corruption.
7. How can I test production data conditions without copying production data?
Use a representative sample that preserves important distributions and supplement it with deliberately constructed edge cases. Run separate scale tests when necessary for performance validation.
8. What is the fastest way to test whether a pipeline is safe to rerun?
Interrupt a pipeline during a write, run it again with the same input, and compare the resulting state with a clean single execution. Then repeat the test with duplicate keys and late-arriving records.
Related Reads
- How to Build AI-Native Applications for Enterprise Scale
- How to Build an Enterprise Context Layer for AI
- AI-Native DevOps: How to Build CI/CD Pipelines for AI-Powered Applications
- How Context Engineering Reduces AI Hallucinations
- How to Modernize Legacy Applications Without Rewriting
- AI Context Engineering: The New Competitive Advantage for Enterprise AI