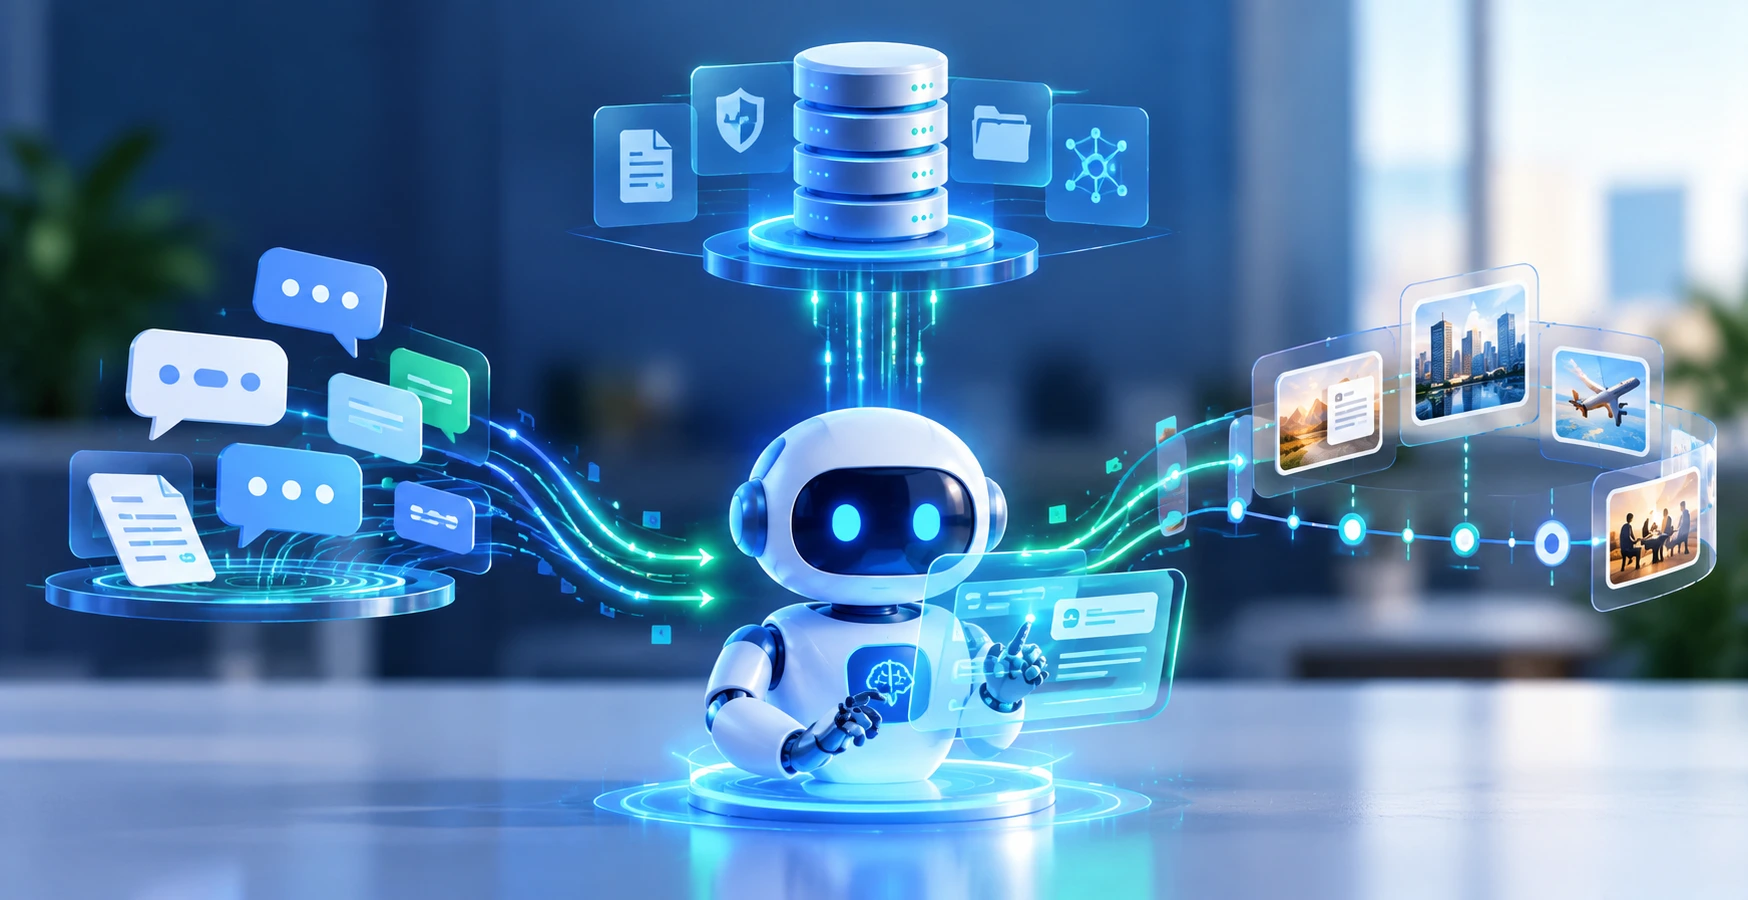
AI agent memory architecture defines how agents store, retrieve, update, and forget information. Short-term memory maintains context during an active task, long-term memory preserves useful information across sessions, and episodic memory records past experiences and outcomes. Combining these types helps agents maintain continuity, reuse relevant knowledge, and execute workflows more reliably.
AI agents are becoming more capable of handling multi-step tasks, interacting with enterprise systems, and supporting decisions across extended workflows. But without an effective memory architecture, an agent may forget earlier instructions, repeat failed actions, or lose important context between sessions. Agent memory architecture is the combination of storage, retrieval, update, and governance mechanisms that enables AI agents to retain and reuse relevant information over time. By combining short-term memory, long-term memory, and episodic memory, enterprises can build agents that maintain context, recall useful experiences, and improve task execution without treating every interaction as a fresh start.
For organizations moving from AI chatbots to production-grade AI agents, memory architecture is a critical part of system design. The challenge is not to remember everything. It is to preserve the right information, retrieve it at the right time, and ensure it remains accurate, secure, and useful.
Executive Summary
Agent memory architectures determine how AI agents preserve context during a task, retain knowledge across sessions, and reuse information from past experiences. Short-term memory supports the current interaction, long-term memory stores information that remains useful over time, and episodic memory records specific past events, actions, and outcomes.
These memory types serve different purposes and are often combined in a single architecture. A production AI agent may use working state for an active workflow, semantic memory for stable business facts, episodic memory for previous task outcomes, and procedural memory for instructions or validated workflows.
The right architecture depends on task duration, personalization requirements, data sensitivity, retrieval latency, and the cost of incorrect recall. Enterprises should design memory as a managed information lifecycle—not simply a conversation-history database or vector store.
TL;DR
- Short-term memory keeps the information an agent needs for the current conversation or task.
- Long-term memory preserves useful facts, preferences, knowledge, and instructions across sessions.
- Episodic memory stores specific experiences, including what happened, what actions were taken, and what the outcomes were.
- Semantic memory represents stable facts and concepts; procedural memory captures how an agent should perform a task.
- Retrieval-augmented generation (RAG) can help an agent retrieve relevant information, but retrieval alone does not constitute a complete memory architecture.
- Enterprise-ready memory requires selective writes, relevance-based retrieval, expiration policies, access controls, evaluation, and deletion workflows.
- The best approach is usually hybrid: combine session state, structured storage, searchable memory, and validated business knowledge according to the use case.
What Is an Agent Memory Architecture?
An agent memory architecture is the system that determines what an AI agent remembers, where information is stored, how it is retrieved, when it is updated, and when it should be forgotten. It connects an agent’s runtime context with persistent information so the agent can maintain continuity across turns, sessions, and tasks.
Unlike a basic chatbot that relies primarily on the context supplied in a single request, a memory-enabled agent can retrieve relevant information from previous interactions or completed workflows.
A memory architecture typically includes five components:
- Memory capture: Identifies useful information from user messages, tool calls, observations, and task outcomes.
- Memory storage: Persists information in session state, databases, document stores, vector indexes, or other suitable systems.
- Memory retrieval: Selects relevant information based on the current task, user, permissions, and context.
- Memory management: Updates, summarizes, consolidates, expires, or removes stored information.
- Memory governance: Controls access, privacy, provenance, retention, and auditability.
These components work together. A database can preserve every conversation, but that does not mean the agent can retrieve the right information or use it correctly. Effective memory requires both persistence and a reliable process for selecting relevant context.
Why does AI agent memory matter?
Memory reduces the need to reconstruct context from scratch and can help agents maintain continuity across longer workflows. It also enables personalization, reuse of prior task outcomes, and more consistent execution of recurring processes.
Consider an enterprise procurement agent. During one session, it learns that a purchase request requires finance approval. Later, it encounters a similar request. If the relevant policy or validated workflow is available in memory, the agent can use it instead of relying on the user to repeat the instruction.
However, memory does not automatically make an agent learn correctly. Stored information can be outdated, irrelevant, incomplete, or maliciously influenced. The architecture must decide which information is trustworthy and whether it remains appropriate to reuse.
The Three Core Types of Agent Memory
Short-term, long-term, and episodic memory describe different aspects of an agent’s ability to retain information. Short-term memory focuses on the active task, long-term memory concerns information that persists across tasks, and episodic memory records particular experiences that may inform future behavior.
These categories are complementary, not mutually exclusive. Episodic memory is commonly implemented as a form of persistent memory, while short-term memory can temporarily contain information retrieved from long-term or episodic stores.
1. Short-Term Memory: Context for the Current Task
Short-term memory is the information an agent uses to maintain continuity during an active conversation, workflow, or task. It can include recent messages, tool results, intermediate task state, retrieved documents, unresolved questions, and outputs generated during execution.
In agent frameworks, this is often managed as session state or thread-scoped state. For example, LangGraph uses checkpoints to persist thread state, while the OpenAI Agents SDK provides session mechanisms for retaining conversation history across runs.
Example: A customer-support agent investigates a delayed shipment. Its short-term memory tracks the order number, carrier response, delivery status, troubleshooting steps, and information still needed to resolve the case.
What should short-term memory contain?
- Recent conversation turns relevant to the task.
- Current objectives and constraints.
- Tool calls and their results.
- Intermediate workflow state.
- Outstanding actions and dependencies.
- A compact summary when the full history is too large.
Advantages
- Supports coherent multi-turn interactions.
- Helps agents resume interrupted workflows.
- Keeps current task information available to subsequent steps.
- Enables coordination between tools or specialized agents when state is shared appropriately.
Limitations
Short-term memory can become too large as conversations and tool outputs accumulate. Sending the entire history to a model can increase latency and token costs, while irrelevant or stale content may distract the model. Context windows are finite, and even long-context models can struggle when the relevant information is buried in a large input.
Best practice: Keep the active state focused. Summarize completed work, retain unresolved decisions, and retrieve older details only when needed.
2. Long-Term Memory: Information That Persists Across Sessions
Long-term memory stores information that remains useful beyond the current task or conversation. It can include user preferences, stable facts, application-specific knowledge, organizational context, validated instructions, and recurring workflow requirements.
Unlike session memory, long-term memory is usually organized so that information can be retrieved across multiple conversations or tasks. LangGraph, for example, distinguishes thread-scoped checkpoints from stores used for cross-thread memory.
Example: An enterprise analytics assistant remembers that a business unit uses an approved definition of customer churn and prefers financial reports grouped by fiscal quarter. It can reuse those details in future reports, provided the information is still valid and the user is authorized to access it.
Common types of long-term memory
- User memory: Preferences, recurring requirements, and user-provided context.
- Semantic memory: Stable facts, concepts, entities, and relationships.
- Procedural memory: Instructions, workflows, skills, and validated operating rules.
- Organizational memory: Approved business definitions, policies, and shared knowledge.
Advantages
- Enables personalization across sessions.
- Reduces repeated instructions.
- Supports reusable knowledge and task conventions.
- Helps maintain consistency across recurring workflows.
Limitations
Long-term memory introduces challenges around staleness, conflicting information, privacy, access boundaries, and inappropriate persistence. A preference recorded months ago may no longer be correct. A business rule may have changed. A fact associated with one user must not inadvertently influence another user’s experience.
Best practice: Store information selectively, attach provenance and timestamps, distinguish confirmed facts from inferred preferences, and provide mechanisms to correct or delete memories.
3. Episodic Memory: Learning from Specific Experiences
Episodic memory stores records of particular past events or task executions. Instead of preserving only a general fact, it captures what happened in a specific situation, what actions were attempted, and what outcome followed.
For AI agents, an episode might include the task objective, relevant context, tools used, decisions made, errors encountered, final outcome, and feedback. When a similar task occurs, the agent can retrieve the episode as a precedent or example.
Example: A software engineering agent previously attempted a code migration, encountered a dependency conflict, applied a specific fix, ran tests, and successfully completed the migration. When it encounters a comparable project, it can retrieve that experience and use it to inform its next steps.
What should an episodic memory record contain?
A useful episode may include:
- Task description and initial conditions.
- Relevant environment or system state.
- Actions and tool calls.
- Significant observations and decisions.
- Failures, retries, and corrective steps.
- Final outcome and verification evidence.
- User feedback or evaluation results.
- Timestamp, source, and applicable permissions.
Advantages
- Provides examples from previous task executions.
- Helps agents avoid repeating known mistakes.
- Supports troubleshooting and long-running workflows.
- Creates evidence that can inform future procedural improvements.
Limitations
Past experiences are not guaranteed to apply to new situations. An action that succeeded under one environment or policy may fail elsewhere. Storing every trace without filtering also creates a retrieval problem: the system may surface lengthy, low-value episodes instead of the one that matters.
Best practice: Store meaningful episodes, retrieve them by task similarity and relevant constraints, and distinguish historical evidence from current instructions.
Read more about How to Evaluate an AI Agent Platform: Enterprise Checklist
Semantic Memory vs. Episodic Memory vs. Procedural Memory
Long-term memory can be organized by the kind of information an agent needs to retain. Semantic memory represents what is known, episodic memory represents what happened, and procedural memory represents how a task should be performed. This distinction helps engineers select storage formats and retrieval strategies instead of treating all remembered information as interchangeable text.
| Memory type | What it stores | Example | Common representation |
|---|---|---|---|
| Short-term / working | Current task context and state | Active support case and unresolved steps | Session state, checkpoints, context summaries |
| Semantic | Facts, entities, preferences, and concepts | Approved churn definition | Structured records, knowledge graphs, searchable documents |
| Episodic | Specific experiences and outcomes | Previous incident and verified resolution | Event records, task traces, episode summaries |
| Procedural | Instructions, skills, and workflows | Steps required to approve a purchase | Versioned instructions, workflow definitions, validated skills |
A practical architecture can use all four. For example, a service agent may keep the active case in short-term memory, retrieve the customer’s account facts from semantic memory, inspect similar resolved incidents from episodic memory, and follow an approved escalation procedure from procedural memory.
This separation is useful because each memory type has different update rules. A factual record may need correction when a source system changes; an episode may remain as historical evidence; and a procedure may require formal review and versioning before deployment.
How Does an AI Agent Memory Architecture Work?
A memory-enabled agent typically follows a read–reason–act–write cycle. It identifies the task, retrieves relevant context, uses that context to plan or execute actions, evaluates the outcome, and selectively stores information that may be useful later.
The exact sequence depends on the agent framework and application, but the following pattern is a useful reference architecture.
Step 1: Receive the task and establish context
The agent receives a request, identifies the current user and task, and loads the state needed to continue the workflow.
This may include recent messages, the active workflow checkpoint, task constraints, and any relevant application state.
Step 2: Retrieve relevant memories
The memory subsystem searches for information related to the task. It may use exact keys, structured filters, keyword search, vector similarity, graph traversal, or a combination of these techniques.
Retrieval should consider more than similarity. Recency, authority, task relevance, permissions, and source reliability can all affect whether a memory should be used.
Step 3: Assemble the working context
The system selects a limited set of relevant memories and places them into the model’s active context or makes them available through tools.
It should avoid loading the entire memory store. Only the information likely to improve the current task should consume the model’s working context.
Step 4: Reason and execute
The agent uses the current request and retrieved context to plan, call tools, ask clarifying questions, or perform approved actions.
For consequential tasks, the system should verify important facts and enforce business rules outside the model wherever possible.
Step 5: Evaluate the outcome
The agent or application checks whether the task succeeded. Evidence may include test results, API responses, database state, human feedback, or explicit business validation.
A confident model response alone is not proof that the task was completed successfully.
Step 6: Write or update memory
The system decides whether the interaction contains information worth preserving. It may save a stable fact, update a preference, record a useful episode, or propose an improvement to a procedure.
Not every conversation should create a permanent memory. Some interactions should remain only in the audit history or be deleted according to retention policy.
Step 7: Maintain and forget
Memory records may require deduplication, conflict resolution, expiration, correction, access revocation, or deletion.
This final stage is essential. A memory architecture that can write information but cannot reliably update or remove it will become less trustworthy over time.
Reference Architecture for Enterprise AI Agent Memory
A production memory architecture should separate active workflow state, persistent memory stores, retrieval and ranking, and governance controls. This makes it easier to scale storage independently, use the right retrieval method for each memory type, and apply access and retention rules consistently.
A practical architecture includes the following layers.
1. Agent runtime
The LLM, orchestration framework, tools, and current task state.
2. Memory orchestration layer
The logic that determines what to retrieve, how to rank results, which information can be written, and how context is assembled.
3. Memory storage layer
- Session store or checkpoint database for active tasks.
- Relational or document storage for structured facts and records.
- Vector index for semantic retrieval where appropriate.
- Event or trace store for task episodes.
- Knowledge base or graph for approved domain knowledge and relationships.
- Versioned instruction store for procedural memory.
These are architectural options, not mandatory products. A small agent may use only a database and session store; a larger system may need multiple backends.
4. Governance and control layer
- Identity and access management.
- Tenant and user isolation.
- Provenance and timestamps.
- Retention, expiration, and deletion.
- Encryption and sensitive-data controls.
- Audit logs and evaluation.
5. Evaluation and observability layer
Measures retrieval relevance, memory correctness, task success, latency, cost, and failure patterns.
Architecture flow
User request → Load active state → Retrieve authorized memories → Rank and filter → Assemble context → Execute task → Verify outcome → Selectively update memory → Apply retention and governance policies.
This design separates three concerns that are often mistakenly combined: the history of what happened, the durable knowledge retained from it, and the context presented to the model on a particular run.
Read our blog on AI Coding Agents in Enterprise Software Development: Use Cases, Risks & Best Practices
Choosing the Right Memory Storage and Retrieval Strategy
No single database or retrieval method is best for every kind of agent memory. The storage choice should follow the structure of the information, the way it will be queried, the freshness requirements, and the security constraints.
| Storage or retrieval approach | Best suited for | Main consideration |
|---|---|---|
| Session state and checkpoints | Active conversations and resumable workflows | State size, durability, and session isolation |
| Relational database | Structured facts, metadata, and transactional records | Schema design and query patterns |
| Document store | Flexible memory records and episode summaries | Consistency, indexing, and metadata quality |
| Vector search | Finding semantically similar text or experiences | Similarity is not the same as truth or authority |
| Keyword or full-text search | Exact phrases, identifiers, and terminology | Synonyms and conceptual similarity may be missed |
| Knowledge graph | Connected entities and relationship traversal | Modeling and maintenance complexity |
| Hybrid retrieval | Queries requiring semantic, exact, and structured matching | Ranking, latency, and operational complexity |
When should you use a vector database?
A vector database is useful when the agent needs to retrieve semantically similar content, such as past troubleshooting episodes or relevant notes written in natural language.
It is less suitable as the sole source of truth for values that require exactness, such as current account balances, authorization status, or an approved financial calculation. Those values should generally be retrieved from authoritative systems.
When should you use structured storage?
Structured storage is appropriate for stable attributes, identifiers, preferences, statuses, and metadata that need predictable filtering or updates.
For example, a customer preference may be stored as a structured record with a value, source, timestamp, and confidence indicator rather than as a long paragraph that must be interpreted on every retrieval.
When should you use hybrid retrieval?
Hybrid retrieval is useful when the agent must combine exact filters, semantic similarity, and business relationships. A support agent may first filter episodes by product and software version, then use semantic similarity to identify comparable incidents, and finally verify the current resolution against authoritative documentation.
The design goal is not to adopt the most sophisticated retrieval stack. It is to use the simplest approach that reliably retrieves the information the task requires.
Memory Management: What Should an Agent Remember?
An agent should retain information only when it is likely to improve future performance, support an explicit requirement, or satisfy an approved audit or operational need. The memory write process should assess usefulness, reliability, sensitivity, persistence, and the cost of storing and retrieving the information.
A practical memory policy can use the following questions:
- Future usefulness: Is this likely to matter in a later task?
- Reliability: Did the information come from a trusted source or verified outcome?
- Specificity: Does it apply to one user, one task, one organization, or a broader domain?
- Sensitivity: Does it contain personal, confidential, or regulated information?
- Freshness: Could the information become outdated?
- Actionability: Will storing it help the agent make a better decision?
- Retention: How long should it remain available?
Memory extraction and consolidation
Conversation logs and execution traces can be useful evidence, but they should not automatically become long-term memory.
A consolidation process can extract stable facts, useful preferences, significant episodes, and validated lessons. It can also merge duplicates, flag contradictions, and discard low-value details.
For example, if a user corrects the format of three reports, the system may propose a reusable formatting preference. If a coding agent fails because of a specific library incompatibility, it may preserve the episode and the verified resolution. The architecture should not automatically convert every single failure into a universal rule.
Memory decay and expiration
Some information remains useful for years; other information becomes obsolete within minutes.
A robust system can apply different retention rules to different records:
- Active task state expires when the workflow is complete, subject to recovery requirements.
- Temporary observations may have short time-to-live periods.
- User preferences may persist until corrected or deleted.
- Operational facts should be refreshed from authoritative sources.
- Episodes may be retained for an approved period, with sensitive content removed where appropriate.
- Procedures should remain valid only while their approved version is current.
Memory decay does not always mean deleting the entire record. It can mean lowering retrieval priority, marking the record as stale, or requiring revalidation before use.
Read our blog on Build vs Buy AI in 2026: A Strategic Enterprise Decision Guide
Security, Privacy, and Governance for Agent Memory
Memory expands an agent’s effective access to information over time, so it must be treated as a governed data asset. Enterprises should define what can be stored, who can retrieve it, how long it persists, how users correct it, and how it is removed when no longer needed.
1. Prevent cross-user and cross-tenant leakage
Memory retrieval must enforce user, tenant, role, and data-domain boundaries. Do not rely on the model to ignore information that should never have been retrieved.
Apply authorization filters at the retrieval and storage layers, and test with users who have different permissions.
2. Track provenance and trust
Each memory should have enough metadata to establish where it came from and whether it was verified. Useful fields may include source, timestamp, owner, confidence, sensitivity classification, and expiration date.
When memories conflict, the agent should prioritize authoritative, current sources rather than whichever record is most similar to the query.
3. Defend against memory poisoning
An attacker may try to cause an agent to store false instructions or malicious content for use in future sessions. This risk is especially important when agents can write to shared memory or learn from untrusted documents and tool outputs.
Separate untrusted observations from approved procedures, validate high-impact memory writes, and never let a retrieved memory override higher-priority security controls.
4. Support correction and deletion
Users and administrators may need to correct a stored preference, remove an incorrect fact, or delete information associated with a user. Deletion must cover relevant indexes, replicas, derived summaries, and caches according to the system’s retention and compliance requirements.
5. Keep durable policy outside informal memory
High-impact business rules should not depend solely on a model recalling a previous conversation. Store approved policies in controlled systems and enforce critical permissions, validation, and business constraints in application logic.
Memory can help the agent find and interpret a policy; it should not become the only mechanism enforcing that policy.
How to Evaluate an AI Agent Memory Architecture
Memory quality should be measured by its effect on task performance, not by how much information is stored. A reliable evaluation process tests whether the system retrieves the right memory, avoids misleading context, maintains privacy boundaries, and improves outcomes without excessive latency or cost.
Key evaluation metrics
| Metric | What it measures | Example evaluation |
|---|---|---|
| Retrieval precision | How much retrieved content is relevant | Fraction of retrieved memories judged relevant |
| Retrieval recall | Whether important memories were found | Fraction of required memories retrieved |
| Memory correctness | Whether stored facts match trusted sources | Percentage of audited records that remain valid |
| Task success rate | Whether the agent completes the intended task | Successful verified workflows divided by total attempts |
| Context efficiency | Whether useful information is provided without excessive context | Tokens used per successful task |
| Stale-memory rate | How often outdated memories are retrieved or used | Stale retrieved records divided by audited retrievals |
| Unauthorized retrieval rate | Whether the system exposes information outside the permitted scope | Target: zero in the tested scenarios |
| Latency and cost | The operational overhead of memory | Added retrieval time and cost per task |
The exact definitions should be documented so teams can compare results consistently.
Test scenarios that matter
- The correct memory exists and should be retrieved.
- Several similar memories exist, but only one is applicable.
- The memory is stale or contradicted by a current authoritative source.
- No relevant memory exists and the agent should say so.
- A memory belongs to another user or tenant.
- A malicious instruction appears inside a retrieved episode.
- The user asks to correct or delete a stored preference.
- A long workflow is interrupted and must resume from a checkpoint.
Run these tests against a baseline agent without persistent memory. This helps determine whether the memory architecture improves task success enough to justify its added complexity and operating cost.
A Practical Implementation Roadmap for Enterprise AI Agents
A phased implementation reduces the risk of introducing persistent memory before the organization understands what information should be retained and how it will be governed. Start with short-term state, introduce a narrowly scoped long-term memory, add episodic retrieval when there is a measurable use case, and expand after evaluation.
Phase 1: Define the memory requirements
Choose a business workflow and determine whether it needs conversation continuity, personalization, reusable facts, past-experience retrieval, or all four.
Define success metrics and identify sensitive data before choosing a storage technology.
Phase 2: Implement short-term memory
Persist the state required to continue an active workflow. Include the current objective, important messages, tool outputs, completed steps, and outstanding actions.
Add checkpointing and recovery behavior if the workflow may be interrupted or take a long time to complete.
Phase 3: Add selective long-term memory
Choose a small set of useful, well-defined records, such as approved preferences or user-specific workflow settings. Add provenance, access boundaries, correction, and deletion controls.
Avoid persisting full conversation transcripts unless there is a clear operational or compliance requirement.
Phase 4: Introduce episodic memory
Capture meaningful task executions, including the conditions, actions, failures, and verified outcomes. Retrieve episodes only when they are relevant to the current task.
Use structured metadata and filters to narrow candidates before semantic ranking when appropriate.
Phase 5: Evaluate and refine retrieval
Build a representative test set. Measure retrieval relevance, task success, staleness, latency, and cost. Adjust extraction, ranking, summarization, and expiration policies based on observed failures.
Phase 6: Establish production governance
Define ownership, monitoring, retention, security reviews, model and prompt changes, and procedures for correcting bad memories.
Expand to additional users and workflows only after the system demonstrates reliable performance and appropriate controls.
Common Mistakes in AI Agent Memory Design
The most common memory failures arise from storing too much, retrieving without sufficient filtering, confusing historical examples with authoritative rules, and failing to manage data over time. These mistakes can make an agent less reliable even when its model and storage infrastructure are capable.
Mistake 1: Treating the entire conversation history as memory
Conversation history is useful evidence, but not every message is worth retrieving indefinitely.
Better approach: Summarize current state, extract useful durable information, and retain raw history only when required.
Mistake 2: Assuming a vector database solves memory
A vector store can help retrieve similar content, but it does not determine which information is true, current, authorized, or appropriate to retain.
Better approach: Combine retrieval with metadata, source validation, access controls, and explicit memory policies.
Mistake 3: Storing unverified lessons as permanent rules
An agent may misdiagnose a failure or succeed for reasons unrelated to its chosen action.
Better approach: Store the episode as historical evidence, verify the outcome, and require validation before promoting a lesson into procedural memory.
Mistake 4: Ignoring contradictory or outdated memories
Old preferences and obsolete operational facts can conflict with current information.
Better approach: Use timestamps, versioning, source authority, expiration, and conflict-resolution rules.
Mistake 5: Forgetting privacy and deletion
Persisted memory may contain personal, confidential, or regulated information.
Better approach: Apply data minimization, scoped access, retention limits, and verified deletion across relevant stores and indexes.
Mistake 6: Measuring memory by volume
A larger memory store does not necessarily make an agent more intelligent or effective.
Better approach: Measure whether the right information was retrieved and whether it improved the verified outcome.
The Future of Agent Memory Architectures
Agent memory is evolving from simple conversation-history persistence toward systems that selectively capture experiences, maintain compact representations, and retrieve context when needed. Research and implementation patterns increasingly emphasize the separation of stored information from the mechanisms used to index and retrieve it, helping agents manage long-running tasks without continuously loading every historical detail.
Several developments are particularly relevant to enterprise architecture:
- More selective memory formation: Systems will increasingly distinguish useful lessons from raw traces and routine interactions.
- Context-aware retrieval: Retrieval may combine semantic similarity with task state, source authority, time, permissions, and workflow constraints.
- Memory consolidation: Repeated episodes may be summarized into more reusable facts or validated procedures.
- Shared and multi-agent memory: Multiple agents may use common business context, requiring stronger ownership and access controls.
- Better memory evaluation: Teams will need systematic tests for relevance, correctness, staleness, privacy, and task outcomes.
- Governed forgetting: Retention, correction, expiration, and deletion will become core parts of memory lifecycle design.
These are architectural directions rather than guaranteed capabilities of every agent framework. Enterprises should validate the maturity and behavior of their chosen tools before adopting them for critical workloads.
How Techment Can Help Build Enterprise AI Memory Architectures
Building reliable AI agent memory requires more than selecting a vector database or increasing a model’s context window. It requires an architecture that connects data engineering, agent orchestration, retrieval, security, evaluation, and business processes.
Techment helps enterprises design and implement AI solutions through enterprise AI strategy, data engineering, RAG architectures, AI agent development, cloud modernization, and enterprise software engineering.
For organizations moving from AI prototypes to production agents, a memory architecture assessment can identify what information should be retained, which retrieval patterns fit the use case, how memory should be governed, and which metrics will demonstrate measurable business value.
The goal is not to build an agent that remembers everything. It is to build one that remembers the right things, retrieves them reliably, and knows when they should no longer be used.
Frequently Asked Questions
1. What is memory in AI agents?
Memory in AI agents is the mechanism used to preserve and retrieve information from current or past interactions. It can support task continuity, user personalization, reuse of previous experiences, and more consistent execution across sessions.
2. What are the three main types of AI agent memory?
The three commonly discussed types are short-term memory, long-term memory, and episodic memory. Short-term memory supports the current task, long-term memory retains information across tasks, and episodic memory records specific experiences and their outcomes. Semantic and procedural memory are also important categories for designing long-term memory.
3. What is the difference between short-term and long-term memory in AI agents?
Short-term memory keeps context for an active conversation or workflow, while long-term memory preserves useful information across sessions. Short-term memory may contain temporary tool results and task state; long-term memory may contain stable preferences, facts, knowledge, and instructions.
4. What is episodic memory in AI agents?
Episodic memory stores records of specific past experiences, including the task, relevant conditions, actions, observations, and outcomes. Agents can retrieve relevant episodes to inform similar future tasks, but past outcomes should be verified before being treated as reusable rules.
5. How is semantic memory different from episodic memory?
Semantic memory stores facts, concepts, and relationships, while episodic memory stores records of specific events and experiences. For example, an approved refund policy is semantic or procedural knowledge, while the record of a previous refund investigation is episodic memory.
6. Does RAG count as agent memory?
RAG is a retrieval pattern that fetches relevant information and supplies it to a model. It can be part of a memory architecture, especially for retrieving persistent facts, documents, or past episodes, but RAG alone does not define how information is captured, updated, governed, or forgotten.
7. Do AI agents need a vector database for memory?
No. A vector database can help with semantic retrieval, but structured databases, document stores, session state, event records, and knowledge graphs may be more appropriate for other memory types. Choose storage based on data structure, query needs, freshness, access control, and performance requirements.
8. How do you prevent AI agents from remembering incorrect information?
Use selective memory writes, trusted source validation, provenance, timestamps, confidence indicators, and conflict-resolution rules. Test for stale or incorrect recall, and avoid promoting an unverified episode into an authoritative business rule.
9. How should enterprises secure AI agent memory?
Enterprises should enforce user and tenant boundaries, apply least-privilege access, minimize sensitive data retention, audit memory access, and implement correction and deletion processes. Important business rules and authorization decisions should remain enforced by trusted application controls.
10. How do you evaluate an agent memory architecture?
Evaluate retrieval precision and recall, memory correctness, verified task success, stale-memory usage, context efficiency, latency, cost, and unauthorized retrieval. Test cases should include missing, conflicting, outdated, and cross-user memories.
11. Can multiple AI agents share memory?
Yes, if the architecture provides appropriate shared stores or context services. Shared memory can reduce duplicated knowledge across agents, but it requires clear ownership, versioning, access controls, and validation to prevent one agent from introducing incorrect or unauthorized information into another agent’s context.
12. What is the best memory architecture for enterprise AI agents?
There is no single best architecture for every workload. A common starting point is short-term state for active tasks, structured long-term memory for durable facts, episodic storage for meaningful past outcomes, and retrieval mechanisms suited to each data type. Add governance and evaluation from the beginning.
Related Reads
- Build vs Buy AI in 2026: A Strategic Enterprise Decision Guide
- A Complete Guide On Agentic AI Orchestration
- Enterprise AI Strategy in 2026
- Fabric AI Readiness: How to Prepare Your Data for Scalable AI Adoption.
- Agentic AI use cases
- 10 AI data analytics trends in 2026
- AI Agent Evaluation Frameworks Compared (2026)