Introduction
Software engineering is undergoing its most significant transformation since the rise of cloud computing.
As enterprises accelerate investments in generative AI, agentic workflows, and intelligent automation, understanding AI-native architecture is becoming a strategic capability for technology leaders, architects, and engineering teams.
In this guide, we explore what AI-native application engineering means, how it differs from traditional software development, the architectural patterns behind production-ready AI systems, and the engineering practices required to deploy them at scale.
For a deeper dive into production architecture patterns, read our guide to AI-native application architecture – AI-Native Engineering Explained: The Enterprise Guide to AI-Driven Software Development
TL;DR: Key Takeaways
- AI-native is an architectural philosophy, not a feature: intelligence is designed in from day one, not added later.
- LLMs are infrastructure: treat them like databases — with connection pooling, fallback strategies, latency budgets, and SLAs.
- Prompt engineering is software engineering: prompts are code, they need versioning, testing, and deployment pipelines.
- Agentic systems require new orchestration patterns: multi-step reasoning, tool use, memory, and human-in-the-loop checkpoints.
- Observability is non-negotiable: you cannot debug what you cannot see — trace every LLM call, every tool invocation, every decision.
- Evaluation is the hardest part: traditional unit tests do not work for probabilistic systems — evaluation requires new frameworks entirely
What Is AI-Native Application Engineering?
AI-native application engineering is the discipline of designing, building, deploying, and operating software systems where artificial intelligence serves as the primary decision-making and reasoning layer.
For decades, applications were designed around deterministic logic: predefined rules, structured inputs, and predictable outputs. Today, organizations are building a new class of systems where intelligence itself becomes the architecture. These systems can reason, adapt, make decisions, interact using natural language, and execute complex workflows with minimal human intervention.
This shift has given rise to AI-native application engineering.
Unlike traditional software that incorporates AI as an add-on feature, AI-native applications are designed from the ground up with intelligence as the primary mechanism for delivering value. Large language models (LLMs), retrieval systems, memory layers, and autonomous agents become core architectural components rather than external integrations.
In AI-native systems:
- Language becomes the primary interface
- Reasoning replaces rigid business rules
- Context drives decisions
- Agents execute workflows autonomously
- Learning and adaptation become continuous processes
An AI-native application is software built around AI-driven reasoning, planning, and decision-making rather than deterministic workflows.
Instead of relying exclusively on predefined business logic, these systems dynamically interpret user intent, retrieve information, generate responses, and determine actions based on context.
AI-native applications are software systems designed with AI as the core architectural component, enabling reasoning, decision-making, natural language interaction, and autonomous workflow execution.
AI-Native vs AI-Augmented Applications
One of the most common misconceptions in enterprise AI is confusing AI-native applications with AI-enhanced software.
AI-Augmented Applications
AI-augmented software adds intelligence to existing systems.
Examples include:
- CRM platforms with AI-generated summaries
- Search engines with semantic ranking
- Analytics tools with predictive recommendations
The underlying architecture remains unchanged.
AI-Native Applications
AI-native systems are designed around intelligence from inception.
Examples include:
- Autonomous customer service agents
- AI-powered operations platforms
- Intelligent knowledge assistants
- Enterprise workflow automation agents
Here, AI is not a feature.
AI is the application.
| Dimension | AI-Augmented | AI-Native |
|---|---|---|
| Core Logic | Rules-Based | Reasoning-Based |
| User Input | Structured Forms | Natural Language |
| Decision Making | Deterministic | Probabilistic |
| User Experience | Traditional UI | Conversational & Agentic |
| Context Management | Sessions | Persistent Memory |
| Automation | Task-Level | Workflow-Level |
Why Enterprises Are Investing in AI-Native Application Engineering
Organizations are increasingly pursuing AI-native architectures because they unlock capabilities that traditional software cannot easily achieve.
Faster Decision Making
AI systems can analyze large volumes of information and recommend actions in real time.
Improved Employee Productivity
Knowledge workers spend less time searching, summarizing, and coordinating information.
Enhanced Customer Experiences
AI-native systems enable personalized, context-aware interactions at scale.
Operational Efficiency
Autonomous agents reduce manual effort across workflows, support functions, and operational processes.
The Four Pillars of AI-Native Architecture
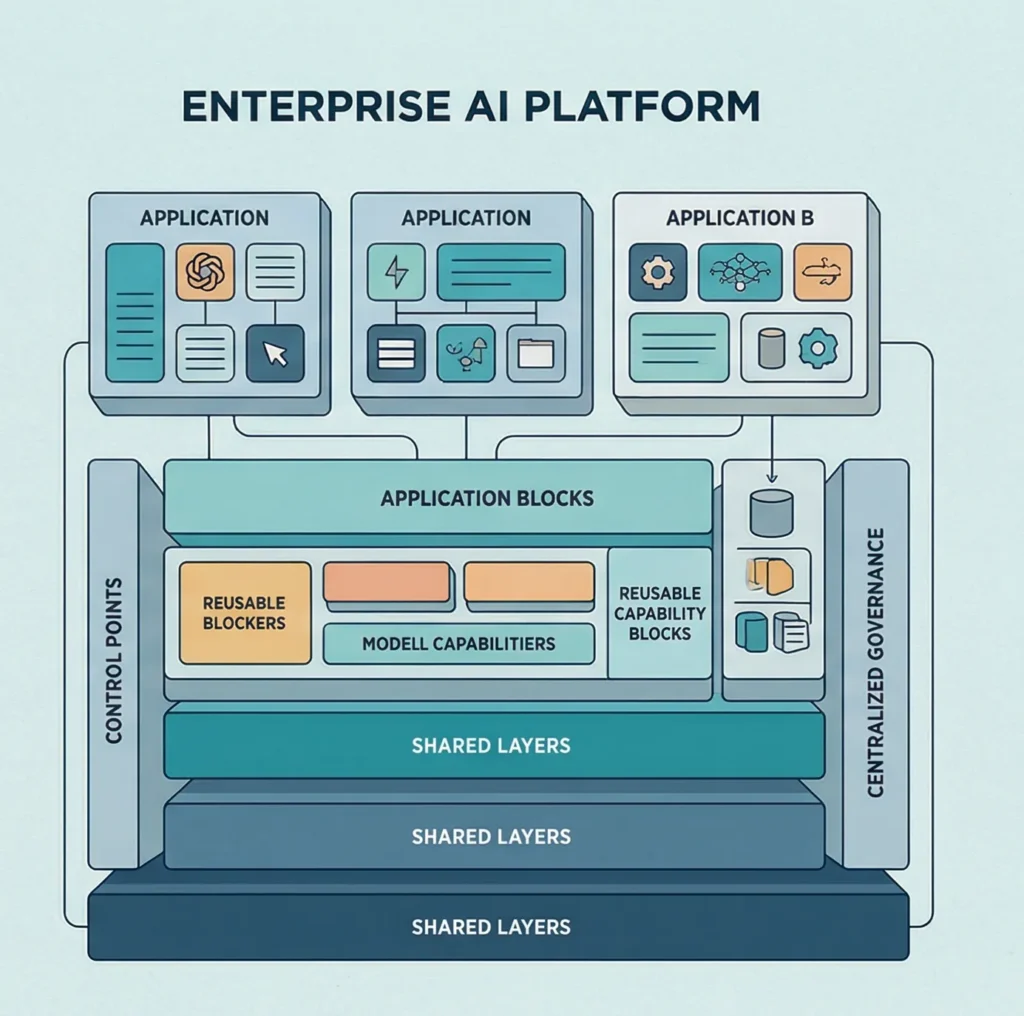
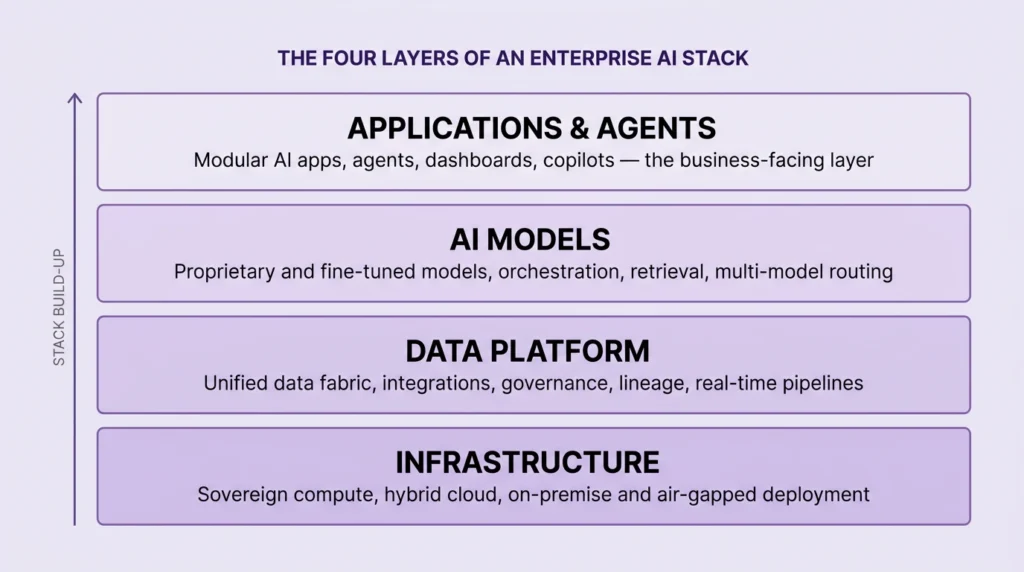
Successful AI-native applications typically rely on four foundational layers.
1. Language Interface Layer
Natural language becomes the primary interaction model.
Users communicate using questions, instructions, and conversations rather than forms and menus.
Examples include:
- Enterprise copilots
- Virtual assistants
- Knowledge agents
- Conversational analytics platforms
2. Reasoning Engine
The reasoning layer interprets intent, plans actions, and generates outputs.
Common responsibilities include:
- Intent understanding
- Decision support
- Task planning
- Content generation
- Multi-step reasoning
Large language models serve as the foundation for this layer.
3. Tool and Data Layer
Reasoning alone is insufficient.
AI systems must access enterprise data and business tools.
Common integrations include:
- Databases
- CRM platforms
- ERP systems
- APIs
- Search engines
- Code execution environments
4. Memory and Context Layer
Context is essential for delivering coherent experiences.
AI-native systems use multiple forms of memory:
- Conversation memory
- Session memory
- Semantic memory
- Long-term enterprise memory
Without memory, every interaction starts from zero.
The Modern AI-Native Engineering Stack
Building production-ready AI systems requires a modern engineering stack.
Large Language Models as Infrastructure
Enterprise teams should treat LLMs similarly to databases and cloud services.
Key considerations include:
- Latency management
- Cost optimization
- Fallback models
- Rate-limit handling
- Version control
- Reliability engineering
Production applications require resilience strategies from day one.
Prompt Engineering as Software Engineering
Prompts represent executable business logic.
Enterprise teams should manage prompts with the same rigor applied to software code.
Best practices include:
- Version control
- Automated testing
- Template management
- Change tracking
- A/B testing
Prompt engineering is increasingly becoming a formal software discipline.
Agentic AI and Autonomous Workflows
One of the most important developments in AI-native architecture is the emergence of agentic systems.
What Is Agentic AI?
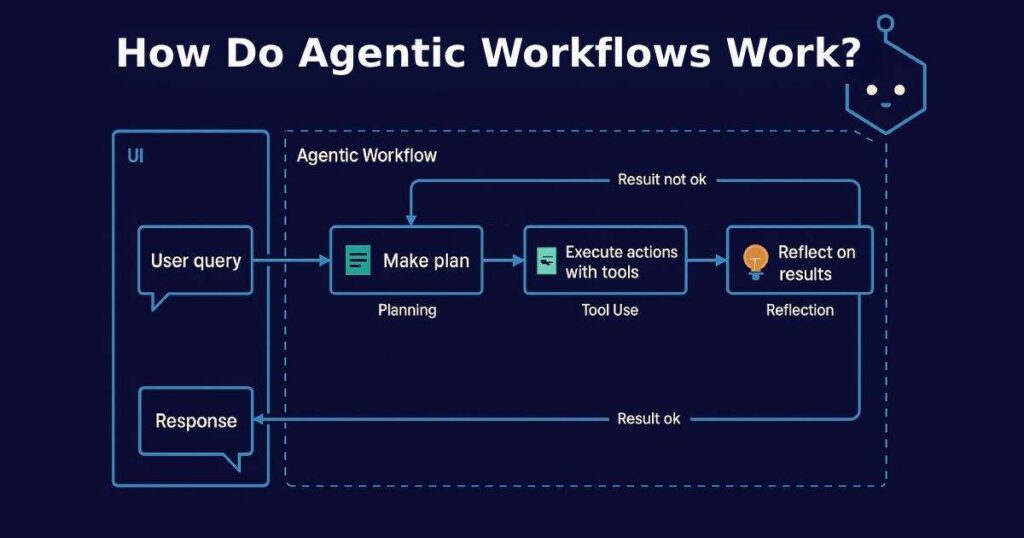
Agentic AI refers to systems capable of independently planning and executing multi-step tasks to achieve defined goals.
Unlike chatbots that simply respond to prompts, agents can:
- Make decisions
- Use tools
- Retrieve information
- Coordinate workflows
- Escalate to humans when necessary
Common Agent Orchestration Patterns
The most powerful — and most complex — AI-native systems are agentic: they do not just respond, they plan and execute multi-step workflows autonomously. Agentic systems introduce patterns that traditional software engineers have never had to reason about:
ReAct (Reason + Act)
The agent reasons about what it needs to do, selects a tool, executes it, observes the result, reasons again, and continues until the task is complete. This is the backbone of most production agents today.
Plan-and-Execute
A planner model produces a structured multi-step plan upfront. An executor model carries out each step. This separation improves reliability on long-horizon tasks where a single model tends to lose track.
Human-in-the-Loop (HITL) Checkpoints
The agent executes autonomously up to a defined confidence threshold, then pauses and routes to a human reviewer before proceeding. This is not a fallback — it is a designed architectural feature for high-stakes decisions.
| Pattern | Best Used When |
| ReAct | Dynamic, unpredictable tasks requiring adaptive tool use |
| Plan-and-Execute | Complex, long-horizon tasks with known structure |
| HITL Checkpoint | High-stakes decisions, regulated domains, low-confidence outputs |
| Parallelised Agents | Independent sub-tasks that can run simultaneously |
| Critic-Revisor | Output quality matters more than speed; self-improvement loop |
Memory Architecture for AI-Native Applications
Ask most engineers where AI-native applications fail in production and memory comes up immediately. Language models have no memory between calls — every invocation starts from a blank slate. Building the illusion of continuity and context is one of the hardest engineering problems in AI-native systems, and it has a direct impact on how useful and coherent the application feels to users. Memory remains one of the most overlooked aspects of AI-native engineering.
The Four Types of Memory
- In-context memory: the conversation history passed directly in the prompt. Fast and simple, but constrained by context window limits (typically 8K–200K tokens depending on model). Does not persist across sessions.
- External short-term memory: a fast key-value store (Redis, for example) that holds session state, recent decisions, and working variables. Survives context window limits, does not survive session end.
- Semantic long-term memory: a vector database (Pinecone, Weaviate, pgvector) that stores embeddings of past interactions, documents, or knowledge. Retrieved at query time via semantic similarity search. The backbone of RAG architectures.
- Structured long-term memory: a relational or document database that stores explicit facts, user preferences, entity state, and relationship graphs. Queried with SQL or graph traversal, not semantic search.
Retrieval-Augmented Generation (RAG) for Enterprise AI
Retrieval-Augmented Generation (RAG) has become a foundational architecture pattern.
What Is RAG?
RAG combines information retrieval with language model generation.
Instead of relying solely on model training data, AI systems retrieve relevant enterprise information before generating responses.
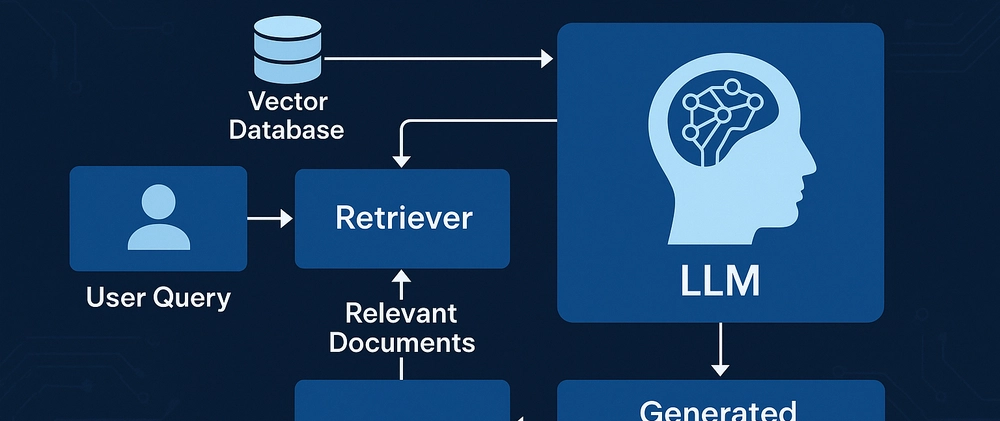
RAG is now a foundational pattern for AI-native applications that need to answer questions grounded in organisational knowledge. The architecture sounds simple — retrieve relevant documents, inject into prompt, generate answer — but production RAG systems are significantly more complex:
- Chunking strategy: how you split documents determines retrieval quality. Fixed-size chunks, semantic chunks, and hierarchical chunks produce very different results.
- Embedding model selection: the embedding model must match the domain. A general-purpose embedding model underperforms on technical or domain-specific corpora.
- Reranking: retrieval returns candidates; a reranker scores them for relevance and filters before injection. Skipping this step causes context pollution.
- Hybrid search: combining dense vector search with sparse keyword search (BM25) consistently outperforms either alone, especially for entity-heavy queries.
- Hallucination grounding: always instruct the model to answer only from retrieved context and to state explicitly when the answer is not in the provided material.
Benefits of RAG
- Improved accuracy
- Reduced hallucinations
- Better explainability
- Access to real-time information
- Enterprise knowledge integration
Enterprise RAG Best Practices
- Semantic chunking
- Hybrid search
- Retrieval reranking
- Metadata filtering
- Source attribution
- Grounded response generation
Organizations implementing RAG effectively often achieve significantly higher answer quality and trustworthiness.
AI Observability and Evaluation
Traditional application observability — latency metrics, error rates, CPU usage — is necessary but nowhere near sufficient for AI-native systems. The system can be responding fast, with zero exceptions, and still be completely wrong. A language model generating confident, fluent, grammatically perfect nonsense produces no exceptions, no 500 errors, and no latency anomaly. Without AI-specific observability, you will never know.
Know more about AI Observability.
Traditional monitoring approaches are insufficient for AI-native systems.
Why AI Observability Matters
An AI system can produce incorrect outputs while generating no technical errors.
Without proper observability, organizations cannot identify:
- Hallucinations
- Quality degradation
- Drift
- Prompt failures
- Agent execution issues
Metrics Every Enterprise Should Track
- Model latency
- Token consumption
- Cost per interaction
- Tool utilization
- Agent success rates
- Response quality
- User satisfaction
AI Evaluation Frameworks
Production AI systems should be evaluated across:
- Faithfulness
- Groundedness
- Relevance
- Coherence
- Safety
- Reliability
Continuous evaluation is essential for maintaining enterprise-grade performance.
Responsible AI-Native Engineering
Building systems that reason and act autonomously carries a qualitatively different level of responsibility than building systems that execute instructions. When a traditional application misbehaves, the failure is usually traceable, deterministic, and reproducible. When an AI-native system misbehaves, the failure may be subtle, probabilistic, and inconsistent — which makes it far harder to detect and far easier to dismiss.
Safety by Design
Safety cannot be a layer added at the end of the development cycle. It must be designed into the architecture from the start:
- Output guardrails: validate and filter every model output before it reaches a user or triggers a downstream action. Build refusal handling for out-of-scope requests.
- Action constraints: for agentic systems, define explicitly what actions the agent is and is not permitted to take. Use allowlists, not blocklists. Restrict by default.
- Escalation paths: define clear conditions under which the system stops acting autonomously and routes to a human. Every autonomous system needs a stop button.
- Audit logs: maintain immutable logs of every autonomous action the system takes, including the reasoning that led to it. This is both a safety mechanism and a regulatory requirement in many domains.
Regulatory and Ethical Landscape
The regulatory environment around AI systems is maturing rapidly. The EU AI Act classifies AI systems by risk level and imposes strict requirements on high-risk applications — including transparency, human oversight, and documentation of training data. The U.S. AI Bill of Rights and NIST AI RMF provide complementary frameworks for responsible deployment.
For AI-native applications specifically, the most common compliance requirements are: explainability of automated decisions, data lineage documentation, bias testing across demographic groups, and documented human oversight mechanisms for consequential actions.
Engineers who understand these requirements and build for them from the start will have a significant competitive advantage. Engineers who retrofit compliance onto systems that were not designed for it will spend enormous effort and still produce fragile results. ders.
Enterprise AI-Native Application Use Cases
AI-native systems are transforming multiple industries.
Healthcare
- Clinical documentation assistants
- Care coordination agents
- Knowledge retrieval systems
Financial Services
- Intelligent compliance workflows
- Risk analysis assistants
- Customer advisory agents
Manufacturing
- Predictive operations agents
- Maintenance copilots
- Supply chain optimization systems
Customer Experience
- Autonomous support agents
- Intelligent service workflows
- Personalized engagement systems
Common Challenges When Building AI-Native Applications
Organizations frequently encounter:
Hallucinations
Generating inaccurate information confidently.
Context Loss
Failing to retain relevant information across interactions.
Tool Reliability
Managing failures across integrated systems.
Cost Management
Controlling token consumption at scale.
Evaluation Complexity
Measuring output quality consistently.
Successful AI-native engineering requires addressing these challenges through architecture, governance, and continuous optimization.
The Future of AI-Native Software Development
The next generation of enterprise software will increasingly be AI-native.
Future applications will feature:
- Multi-agent collaboration
- Persistent memory systems
- Real-time enterprise reasoning
- Autonomous workflow execution
- Multimodal interactions
The organizations that invest early in AI-native engineering capabilities will be best positioned to create intelligent products, accelerate innovation, and improve operational efficiency.
Conclusion
AI-native application engineering represents a fundamental shift in how software is conceived, designed, and operated.
The future of enterprise applications will not be defined by interfaces and workflows alone. It will be defined by systems capable of understanding intent, reasoning through complexity, and taking meaningful action.
Building these systems requires more than access to AI models. It requires disciplined engineering practices, scalable architecture, observability, evaluation frameworks, governance, and responsible deployment strategies.
Organizations that embrace AI-native architecture today are laying the foundation for the next generation of intelligent software systems.
Techment partners with enterprises to design, engineer, and scale AI-native applications—from strategy and architecture through deployment and operational excellence.
FAQs: AI-Native Application Architecture — How Enterprises Build Production-Ready AI Systems
1. What is AI-native application architecture?
AI-native application architecture is a software design approach that integrates AI models, data pipelines, intelligent agents, and application workflows into the core of an application rather than adding AI as a separate feature.
2. How is AI-native architecture different from traditional application architecture?
Traditional architecture primarily relies on predefined rules and deterministic workflows, whereas AI-native architecture incorporates capabilities such as generative AI, contextual reasoning, adaptive workflows, and intelligent automation alongside conventional software components.
3. What are the key components of an AI-native application architecture?
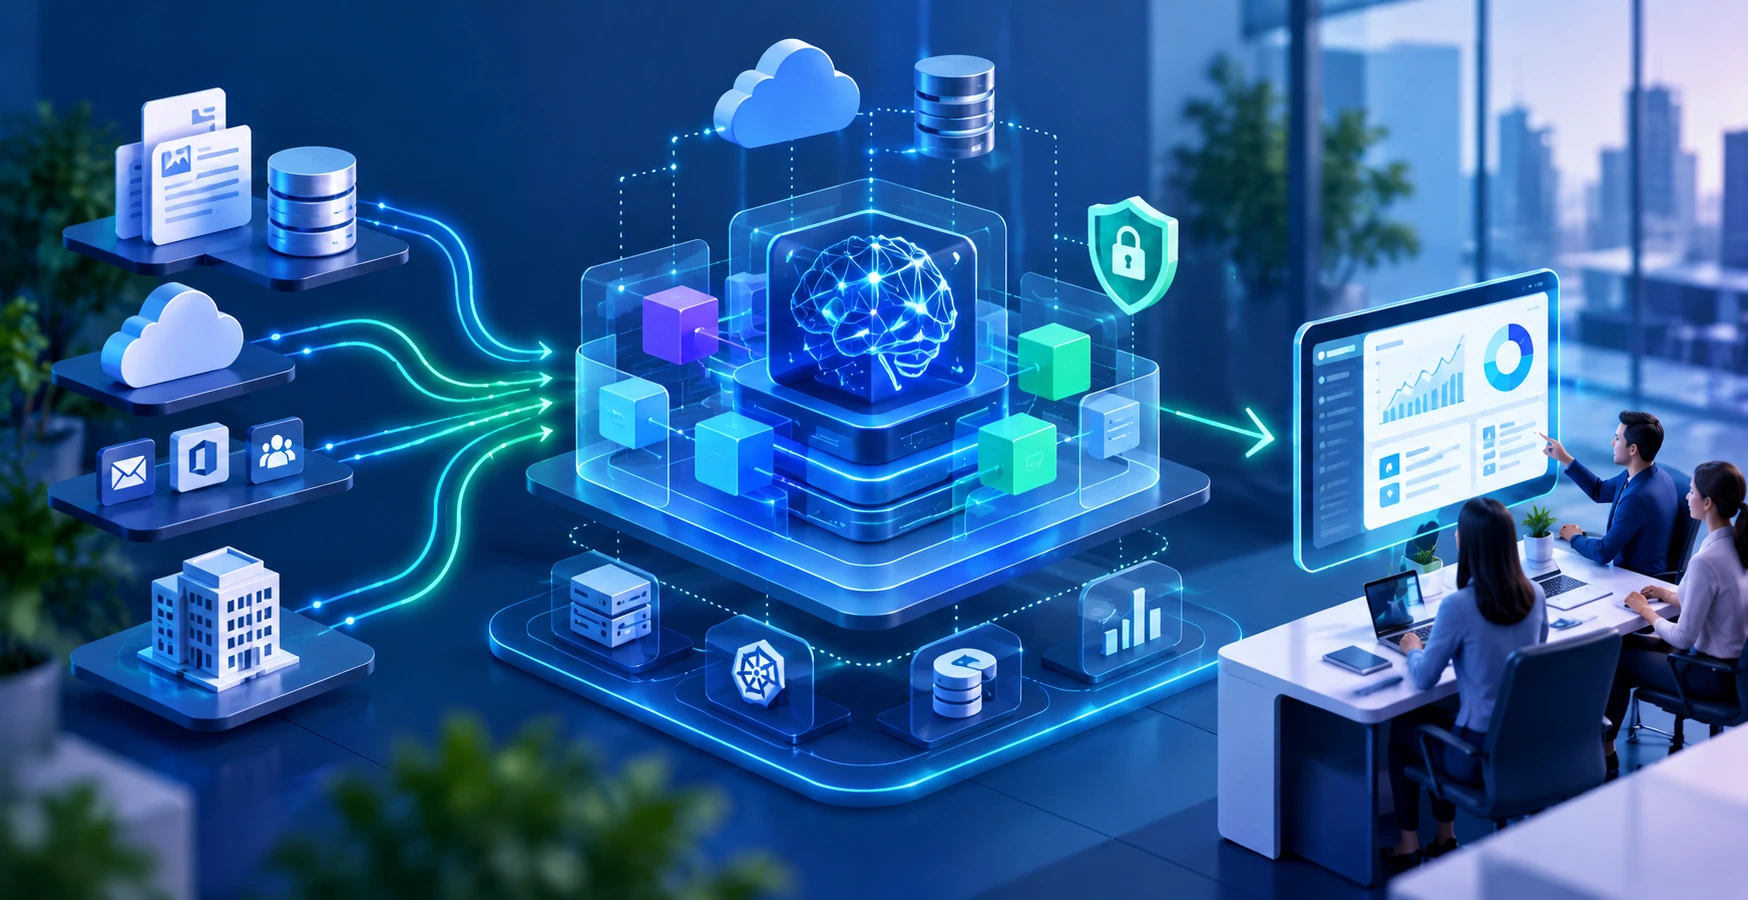
The key components include AI models and inference services, data and knowledge layers, APIs and orchestration, AI agents where needed, security and governance controls, application interfaces, and monitoring systems for performance and reliability.
4. How can enterprises build production-ready AI systems?
Enterprises can build production-ready AI systems by identifying business use cases, establishing a reliable data foundation, selecting appropriate AI models, integrating them into existing applications, implementing security and evaluation frameworks, and continuously monitoring performance in production.
5. What role does RAG play in AI-native applications?
Retrieval-Augmented Generation (RAG) enables AI applications to retrieve relevant information from enterprise documents, databases, and knowledge repositories before generating responses. This helps ground outputs in organizational context and can improve relevance and factual accuracy.
6. Can AI-native applications integrate with existing enterprise systems?
Yes. AI-native applications can integrate with existing enterprise systems through APIs, event-driven architectures, connectors, and controlled tool interfaces. This allows organizations to introduce AI capabilities without replacing their entire technology stack.
7. How can enterprises control the cost of AI-native applications?
Enterprises can control costs by selecting models based on task complexity, caching frequent responses, optimizing retrieval, limiting unnecessary agent iterations, monitoring token usage, and using smaller models for simpler tasks.
Related Reads
- Eval-Driven Development: Building Reliable AI Applications
- How to Evaluate an AI Agent Platform: Enterprise Checklist
- Understanding Spec-Driven Development: A Practical Guide
- Why Data Pipelines Work in Development but Fail in Production: 6 Gaps to Test
- 7 Architectural Patterns for AI-Native Enterprise Applications