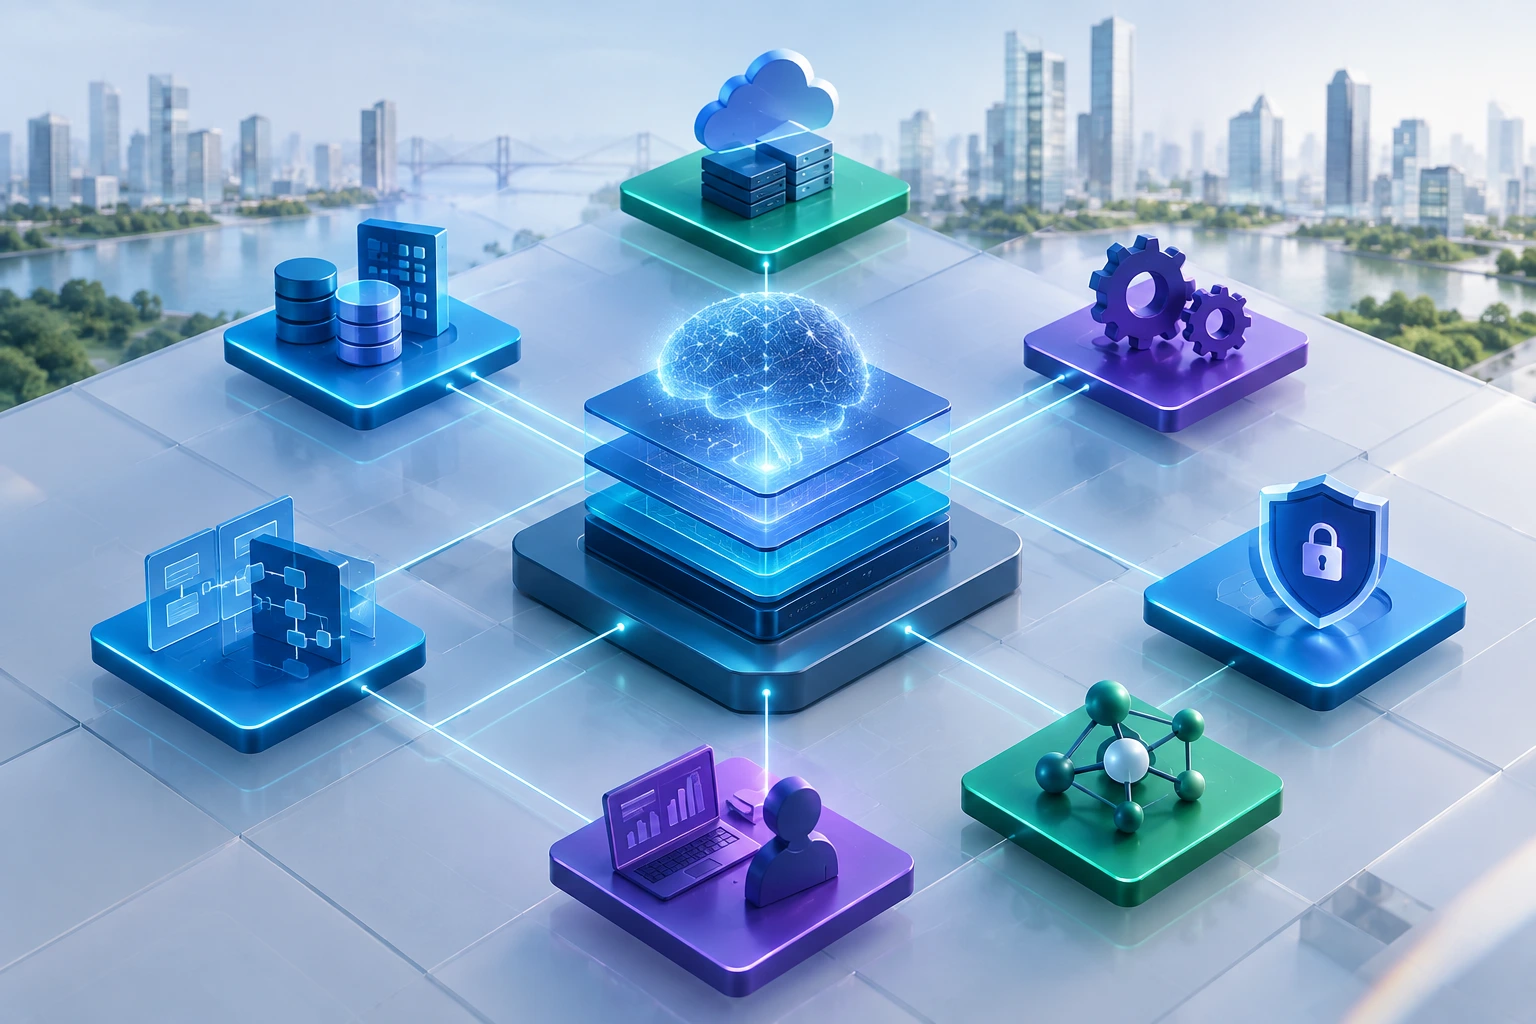

The true value of Generative AI in the enterprise relies on accuracy and trust. While LLMs are powerful, their vulnerability to generating convincing but incorrect information (hallucinations) poses significant liabilities in high-stakes environments—from healthcare and finance to supply chain. This is why building a reliable RAG application has become the single most important architectural challenge for CTOs and data leaders.
This is where Retrieval-Augmented Generation (RAG) has emerged as one of the most important architectural advancements in AI. Instead of relying solely on the internal knowledge of an LLM, RAG enhances the model with access to verified, up-to-date, domain-specific information, dramatically elevating both accuracy and reliability. By grounding responses in curated enterprise data, RAG transforms generative AI from a probabilistic guesser into a trusted system for decision support, automation, and high-precision interactions.
In this in-depth guide, we explore how RAG improves accuracy and reliability in generative AI applications, why it is now a strategic imperative for CTOs and data leaders, and how organizations can successfully implement RAG as part of a scalable AI ecosystem. You’ll learn:
- What RAG is and how it works
- Why accuracy and reliability remain challenges in modern LLMs
- How RAG mitigates hallucinations with retrieval-based grounding
- Enterprise-ready RAG architectures, patterns, and best practices
- Real-world use cases across industries
- Metrics, KPIs, and operational frameworks
- How Techment helps enterprises accelerate RAG adoption
TL;DR
- RAG reduces hallucinations by grounding LLM outputs in enterprise-validated data, improving accuracy and reliability in mission-critical environments.
- It enables domain-specific reasoning, source citation, and auditability, making AI outputs more trustworthy for regulated industries.
- With RAG, enterprises can update knowledge bases without retraining models, ensuring faster scalability and lower operational cost.
- RAG is now a foundational architecture for enterprise-grade generative AI, supporting use cases in support automation, compliance, healthcare, and decision intelligence.
- Techment provides a full-stack RAG implementation capability — from data auditing to vectorization, retrieval engineering, governance, and MLOps.
Strengthen your foundation for reliable generative AI by exploring: Data Integrity: The Backbone of Business Success
2. What is RAG? The Core RAG Application Architecture
Retrieval-Augmented Generation (RAG) is an AI architecture that enhances large language models by grounding their outputs in retrieved, contextually relevant external data. Instead of asking an LLM to rely solely on its internal, pre-trained knowledge—which may be outdated, incomplete, or generic—RAG equips the model with the ability to fetch authoritative information from curated sources before generating a response.
This architecture represents a shift from pure generation to generation + retrieval, ensuring that responses are anchored in factual and domain-specific information. Research from leading AI organizations such as NVIDIA and IBM highlights RAG as one of the most impactful methods for reducing hallucinations and improving the factual accuracy of AI systems.
Core Components of RAG
RAG combines three core pillars that work together to deliver accurate and reliable outputs:
1. Indexing / Embeddings Layer
Enterprise data—documents, manuals, tickets, reports, repositories—is converted into mathematical vectors using embedding models. These embeddings enable the system to understand semantic relationships across large knowledge corpora.
2. Retrieval Module
This component identifies and returns the most relevant chunks of information from a vector store or hybrid indexing system. Tools like FAISS, Pinecone, Weaviate, or Elasticsearch can be used. Some reports that retrieval quality is directly tied to the usefulness of generated output.
3. Grounding Generation in Retrieval for a Strong RAG Application
The LLM uses a context-augmented prompt, incorporating the retrieved documents into its reasoning process. This grounding dramatically reduces hallucinations and injects domain precision. Some platforms showcase significant improvements in answer accuracy using this architecture.
Why RAG Matters
Traditional LLMs are trained on static snapshots of data and cannot easily update their knowledge. RAG addresses this by linking the model to dynamic, enterprise-owned sources of truth, ensuring:
- Fresh, up-to-date information
- Domain-specific accuracy
- Reduced risk of hallucination
- Traceability and verifiability
Brief Evolution and Industry Adoption
RAG methodologies emerged from academic research and quickly gained traction in the enterprise ecosystem. Over the past three years, adoption has accelerated across industries such as healthcare, retail, finance, and logistics—driven by the need for more trustworthy AI outcomes.
RAG is no longer experimental; it is becoming a foundational layer in enterprise GenAI architecture.
Build a stronger data foundation for RAG by exploring: Data Management for Enterprises: Roadmap
3. Why Accuracy & Reliability Are Challenging in Generative AI
Generative AI systems deliver impressive results, but accuracy and reliability remain persistent challenges, especially in enterprise environments where factual precision and explainability are critical. Despite their scale and sophistication, large language models (LLMs) are inherently probabilistic—they predict the next likely token based on training data rather than reasoning from verified sources.
Understanding AI Hallucinations
“Hallucinations” refer to AI-generated responses that are confident but incorrect—a widespread issue documented by Dataversity. These hallucinations stem from how LLMs operate: they synthesize information from patterns in vast datasets rather than retrieving real facts. In consumer applications, occasional inaccuracies may be tolerable. In enterprise applications, however, they can be disastrous.
Why Hallucinations Matter More in Enterprise Contexts
Industries like healthcare, finance, insurance, and legal services require precise, verifiable, and compliant outputs. Incorrect AI-generated information can lead to:
- Compliance violations
- Patient care risks
- Legal exposure
- Incorrect business decisions
- Operational inefficiencies
A single hallucinated answer in a regulatory environment can cause compliance failures or reputational damage.
Limitations of Pure LLMs
IBM highlights several fundamental limitations of stand-alone generative models:
- Training data cutoff limits real-time knowledge.
- No inherent capability to cite sources.
- No built-in verification of factual accuracy.
- Lack of domain context, especially for proprietary enterprise data.
Pure LLMs lack access to live, enterprise-specific data streams—meaning they cannot reliably answer questions about new regulations, updated policies, emerging risks, or recent business changes.
Trust, Transparency & Auditability Gaps
Enterprises increasingly require AI to justify its answers. Without grounding mechanisms, LLMs cannot offer:
- Traceable citations
- Clear sourcing of facts
- Audit trails for compliance
This “black-box” behavior is unacceptable in regulated domains where decisions must be explainable.
The Enterprise Reality: Accuracy Is Non-Negotiable
Rsearch reports that accuracy and trustworthiness are the top two barriers to enterprise AI adoption. Organizations cannot rely on probabilistic models in contexts requiring deterministic, verifiable outputs.
This is precisely why RAG has become a cornerstone for enterprise generative AI maturity—it provides the grounded factuality that pure LLMs lack.
Explore how Techment turns complex data into trustworthy insights: How Techment Transforms Insights into Actionable Decisions Through Data Visualization?
4. How RAG Improves Accuracy & Reliability — The Mechanisms
Retrieval-Augmented Generation (RAG) directly addresses the core weaknesses of large language models by grounding generated outputs in verified, relevant, and constantly updated enterprise data. This section breaks down the key mechanisms through which RAG delivers measurable improvements in accuracy, reliability, and trustworthiness.
1. Grounding Generation in Retrieval
Unlike pure LLM architectures that rely solely on pre-trained parameters, RAG retrieves real-time, domain-specific knowledge from internal repositories, knowledge bases, or external sources. NVIDIA highlights that retrieval-based architectures dramatically reduce the model’s dependence on probabilistic inference by injecting factual context into the prompt.
This grounding ensures:
- Reduced ambiguity
- Higher factual precision
- Stronger contextual alignment with business data
2. Reduced Hallucinations & Improved Factual Correctness
By feeding retrieved facts into the prompt, the LLM becomes a reasoning engine rather than a knowledge database. This transforms the output from probabilistic to verifiable.
3. Citations and Verifiability
RAG architectures can return:
- Source documents
- URLs
- Original excerpts
This ensures auditability and compliance.
4. Scalable Knowledge Updates
Instead of retraining the LLM — a costly and time-consuming process — enterprises can simply update the vector store. According to studies, this is 65–80% cheaper than full model retraining cycles.
5. Domain Specialization at Scale
RAG enables LLMs to behave like domain experts by accessing curated internal datasets — knowledge graphs, SOPs, product docs, regulatory updates, etc.
6. Better Relevance & Context
Retrieval layers ensure that the model responds based on query intent, user persona, and domain context.
Discover how cloud data architecture drives reliable AI: AI-Powered Automation: The Competitive Edge in Data Quality Management
5. Key Implementation for a Reliable RAG Application
1. Data Quality Is Everything
The retrieval output is only as good as the data it indexes. High-quality, well-structured content dramatically boosts relevance.
2. Smart Embedding Choices
Use domain-tuned models for embeddings, adopt hybrid retrieval (sparse + dense), or integrate knowledge graphs to improve precision.
3. Retrieve-Then-Rank for Precision
Advanced pipelines use re-ranking layers (e.g., ColBERT, cross-encoders) to improve relevance before feeding the data to the generator.
4. Latency vs. Accuracy Trade-offs
Retrieval introduces latency. Enterprises must fine-tune:
- number of documents retrieved
- vector search parameters
- caching strategies
5. Governance, Transparency & Logging
Critical for regulated industries:
- Log all retrieval results
- Store conversation context
- Track citations
- Maintain audit trails
6. Domain Adaptation & Enterprise Integration
Connecting structured, semi-structured, and unstructured data from siloed systems is key to high accuracy.
7. Continuous Evaluation & Monitoring
Track accuracy, hallucination rate, relevance, user satisfaction, and model drift to drive ongoing improvement.
See actual enterprise-grade implementation in action: Autonomous Anomaly Detection and Automation in Multi-Cloud Micro-Services environment
6. RAG Application Use-Cases: Delivering Measurable Enterprise Value
Retrieval-Augmented Generation (RAG) is rapidly becoming a foundational capability for enterprise-grade generative AI applications because it connects large language models (LLMs) to verified, real-time, domain-specific knowledge. Unlike generic AI assistants that rely solely on static model parameters, RAG-powered systems produce grounded, accurate, and context-aware insights — dramatically improving reliability across business operations. Below are the most impactful enterprise use cases where RAG consistently delivers measurable value.
1. Customer Support Automation
In customer support environments, accuracy is the difference between resolving a query instantly and escalating it needlessly. RAG-enabled support agents retrieve product manuals, troubleshooting steps, and past case resolutions to provide direct and validated answers. Organizations report 30–50% reductions in resolution time and significant improvements in CSAT scores. Importantly, because RAG surfaces citations, agents and customers gain transparency into sources, increasing trust and reducing operational overhead.
2. Knowledge Management & Internal Q&A
Enterprises struggle with tribal knowledge, siloed documents, outdated SharePoint portals, and scattered Confluence pages. RAG consolidates these assets into a searchable, semantically indexed knowledge repository. Employees can ask specific questions (e.g., policy details, technical configurations, compliance steps) and receive unified, accurate answers. The result: faster onboarding, reduced dependency on SMEs, and improved productivity across teams.
3. Legal, Regulatory & Compliance
In domains where text interpretation is mission-critical, RAG retrieves statutes, legal precedents, regulatory updates, and internal policies to generate reliable summaries and recommendations. This reduces compliance risk and enables legal teams to work with up-to-date, traceable information — a key differentiator in industries like healthcare, insurance, financial services, and telecom.
4. Healthcare & Life Sciences
Clinicians and researchers can ask questions and receive context-specific insights drawn from clinical guidelines, medical journals, genomic databases, and prior patient cases. RAG reduces reliance on generic model knowledge and enhances clinical decision support systems with transparent references.
5. Business Intelligence & Decision Support
Beyond text retrieval, RAG can integrate structured data from dashboards or databases. This enables decision-makers to receive analytical answers supported by real-time metrics and KPIs — transforming BI from a pull-based system into an intelligent conversation layer.
6. Multimodal & Advanced Retrieval Use Cases
Future-ready RAG systems incorporate images, charts, tables, and graphs, enabling sophisticated reasoning across modalities. Industries like manufacturing, radiology, and e-commerce are early adopters of these multimodal RAG patterns.
Explore RAG-driven reliability in healthcare and enterprise data systems: Data-cloud Continuum Brings The Promise of Value-Based Care
7. Challenges & Limitations to Watch
While Retrieval-Augmented Generation is a powerful paradigm, enterprises must approach it with a realistic understanding of its limitations. RAG significantly improves accuracy and reliability but is not a magic switch — it requires disciplined data engineering, thoughtful architecture design, and continuous monitoring.
1. RAG Systems Can Still Hallucinate
Although RAG reduces hallucinations, it does not eliminate them. If retrieval retrieves irrelevant documents, contradicting sources, or low-quality content, the LLM may still produce incorrect or partially grounded responses. Retrieval noise is a major accuracy bottleneck.
2. High Data Maintenance Overhead
RAG systems rely heavily on clean, well-structured, consistently updated knowledge bases. Enterprises must maintain metadata, versioning, deduplication, and content freshness. Without ongoing curation, retrieval relevance degrades, causing model drift in output quality.
3. Security, Privacy, and Compliance Considerations
Centralizing sensitive data in a vector store raises governance requirements. Secure embeddings, token-level access controls, encryption, and careful segmentation of customer/PII data are mandatory — especially in healthcare, BFSI, and public sector deployments.
4. Latency and Performance Trade-offs
As retrieval pipelines grow more complex (multi-step retrieval, re-ranking, graph reasoning), latency increases. Enterprises must balance accuracy with user expectations, cache hot content, and optimize embedding search parameters.
5. Domain Mismatch & Semantic Drift
If embeddings are not trained or adapted to the enterprise’s domain, semantic meaning may be lost, resulting in irrelevant retrievals. Domain adaptation, fine-tuned embeddings, or hybrid retrieval models often become necessary.
6. The Industry Debate: “Is RAG Enough?”
Some industry voices argue that RAG may be replaced by agentic systems or fine-tuning. In practice, enterprises find RAG the most cost-effective, low-risk approach for accuracy and domain grounding — especially compared to expensive, opaque, and slow-to-update fine-tuned LLMs.
See how Techment ensures governance excellence in real enterprise implementations:
Optimizing Payment Gateway Testing for Smooth Medically Tailored Meals Orders Transactions!
8. Measuring Success: KPIs for Your RAG Application
As enterprises adopt RAG, establishing clear, measurable KPIs is essential for ensuring that the system is delivering reliability, transparency, and ROI. Unlike typical AI models that are evaluated solely on accuracy or BLEU scores, RAG-enabled systems require a holistic evaluation spanning retrieval, generation, user trust, and business impact.
1. Hallucination Rate Reduction
One of the primary success metrics. RAG implementations often reduce hallucinations by 25–40%, enabling organizations to measure factual integrity improvements over time.
2. Response Accuracy & Factual Correctness
Enterprises typically rely on:
- Human evaluation panels
- Automated fact-checking
- Ground truth datasets
Accurate grounding in domain-specific knowledge is a top driver of user trust.
3. Retrieval Relevance Scores
Measuring how often the system retrieves correct, contextually relevant, and up-to-date information. Low relevance scores suggest embedding or corpus quality issues.
4. Source Attribution & Citation Rate
A strong RAG system provides transparent citations. Monitoring the percentage of responses that include accurate, traceable references helps evaluate reliability and auditability.
5. Latency & System Performance
Tracking the end-to-end time from query to output ensures user experience is not compromised by complex retrieval pipelines. Performance tuning is crucial for customer-facing applications.
6. Knowledge Update Velocity
RAG enables rapid corpus updates without expensive re-training. KPIs track how quickly new documents, policies, or datasets become available for retrieval.
7. Business-Level KPIs
These ultimately determine ROI:
- Lower support ticket resolution time
- Fewer compliance violations
- Faster onboarding cycles
- Reduced SME dependency
- Efficiency gains in research or analysis teams
8. User Feedback & Satisfaction
Human-in-the-loop evaluation provides real-world signals about precision, clarity, and trust in AI-generated output.
See how RAG-style automation improves enterprise systems at scale:Autonomous Anomaly Detection and Automation in Multi-Cloud Micro-Services environment
9. Roadmap: How to Introduce RAG in Your Organization
Implementing RAG effectively requires a structured, maturity-driven roadmap. Enterprises that rush into RAG without aligning business value, data readiness, and technical architecture often struggle with accuracy, security, and scalability. Below is a proven roadmap for introducing RAG responsibly in enterprise environments.
Step 1 — Identify High-Value Use Cases
Start with scenarios where accuracy is critical and domain knowledge is required: compliance Q&A, customer support, internal knowledge retrieval, clinical guidelines, or legal workflows. These use cases deliver the highest early ROI.
Step 2 — Audit Knowledge Assets
Inventory enterprise documents, data repositories, SharePoint sites, ERP metadata, and historical tickets. Assess freshness, duplication, access control, and quality. Establish a clear taxonomy and versioning strategy.
Step 3 — Select Retrieval & Embedding Architecture
Pick vector stores (Pinecone, Elastic, Weaviate), retrieval frameworks, and embedding models. Consider hybrid retrieval (dense + sparse) or knowledge graphs for improved semantic precision.
Step 4 — Connect Retrieval to Your LLM
Implement retrieval pipelines, context windows, and prompt augmentation templates. Ensure the LLM receives clean, well-curated snippets to generate grounded outputs.
Step 5 — Build Evaluation & Feedback Loops
Establish dashboards for hallucination rate, relevance, accuracy, and latency. Enable SME feedback loops to reinforce retrieval relevance and flag inaccuracies.
Step 6 — Overlays for Governance & Security
Integrate content filters, access controls, encryption, and compliant storage. Maintain audit logs to satisfy regulatory requirements.
Step 7 — Scale Horizontally to Additional Domains
Once the RAG architecture proves reliable, replicate it across departments — HR, finance, operations, legal, engineering — expanding organizational AI maturity.
Step 8 — Continuous Optimization & Innovation
Adopt advanced retrieval patterns: graph RAG, multi-step reasoning, or reranking frameworks (e.g., Corrective RAG, Self-RAG). Introduce domain-tuned embeddings for enhanced relevance.
Advance your enterprise’s data and AI maturity with our whitepaper:Data Cloud Continuum: Value-Based Care Whitepaper
10. Why Partner with Techment for RAG-Enabled Generative AI
Deploying RAG in an enterprise context is not merely about plugging a vector database into an LLM. It requires deep domain expertise, robust data engineering capabilities, and a mature understanding of governance, security, and architectural scalability. This is where Techment stands out as a strategic partner for data-driven enterprises.
1. Deep Expertise in Enterprise Data & AI Architecture
Techment brings years of experience navigating complex enterprise ecosystems — from multi-cloud architectures and legacy modernization to building AI-ready data foundations. Our teams understand the nuances of domain-specific retrieval, knowledge modeling, and context-aware system design.
2. End-to-End Implementation Capability
Techment manages the entire lifecycle:
- Knowledge base audit and cleansing
- Embedding and indexing strategies
- Vector DB selection and setup
- Retrieval pipeline design
- LLM prompt engineering
- Monitoring dashboards
This avoids fragmentation and ensures a coherent, scalable RAG system.
3. Tailored Solutions, Not One-Size-Fits-All
Every industry — healthcare, BFSI, logistics, SaaS — has unique domain language and regulatory obligations. Techment works closely with stakeholders to build RAG systems that reflect your institutional knowledge, business logic, and compliance frameworks.
4. Governance, Trust, and Security First
Accuracy without governance is risky. That’s why Techment builds RAG systems with:
- Comprehensive audit logs
- Source attribution
- Data segmentation
- Prompt-level monitoring
These are essential for regulated environments and high-stakes decisions.
5. Scalable Architectures That Grow With You
Enterprise AI is never static. Techment ensures your RAG stack evolves — from retriever upgrades to embedding recalibration, from expanding corpus coverage to adding multi-modal retrieval capabilities.
6. Business Impact and Real ROI
Techment-designed RAG systems don’t just improve accuracy; they streamline operations, reduce expert dependency, enhance compliance, and unlock new productivity layers across teams.
Unlock value across your entire data ecosystem, Discover Insights, Manage Risks, and Seize Opportunities with Our Data Discovery Solutions
Frequently Asked Questions (FAQs)
1. How does RAG improve accuracy in generative AI compared to standard LLMs?
RAG improves accuracy by grounding each model response in retrieved, verified information rather than relying solely on an LLM’s probabilistic reasoning. Standard LLMs generate answers based on patterns learned during training, which can lead to hallucination or outdated responses. With RAG, the model retrieves relevant enterprise documents, policies, regulatory texts, or product knowledge before producing an answer. This ensures factual correctness, reduces hallucinations by up to 30–40%, and provides traceable citations — making the output far more reliable for mission-critical business applications.
2. What is the ROI of implementing RAG for enterprise use cases?
RAG delivers ROI across multiple dimensions:
- Operational efficiency: Faster employee onboarding, reduced SME dependency, and accelerated decision-making.
- Cost savings: Avoids expensive LLM retraining by updating the retrieval corpus instead.
- Risk reduction: Improved compliance, fewer incorrect outputs, and transparent citations reduce regulatory exposure.
- Customer experience: Higher first-contact resolution in support workflows and improved satisfaction scores.
Most organizations observe meaningful ROI within 3–6 months of deploying targeted RAG pilots.
3. Can RAG work with existing enterprise systems and legacy data sources?
Yes. RAG architectures can integrate with both modern and legacy systems — including SQL-based repositories, SharePoint, Confluence, CRM/ERP systems, cloud data warehouses, and unstructured document libraries. Through ETL pipelines, connectors, and ingestion workflows, Techment ensures your enterprise data becomes accessible, semantically searchable, and securely retrievable for RAG-enabled workflows. Even organizations with fragmented or inconsistent data can start small with curated knowledge bases and scale incrementally.
4. What are the key risks or governance challenges when using RAG?
RAG introduces governance considerations that enterprises must manage carefully:
- Data security: Sensitive documents in vector stores must be encrypted and access-controlled.
- Versioning and freshness: Outdated policies or duplicated content can lead to incorrect retrievals.
- Explainability: Without proper logging and citations, tracking the origin of generated insights becomes difficult.
- Bias and quality: Low-quality source content can propagate errors through retrieval.
To mitigate these risks, Techment embeds governance-by-design, audit trails, data segmentation, and monitoring dashboards into all RAG deployments.
5. How do enterprises measure the success of a RAG implementation?
Success is measured through a mix of quantitative and qualitative KPIs:
- Hallucination rate reduction
- Response accuracy and factual correctness
- Retrieval relevance (precision/recall)
- Citation consistency and source attribution
- Latency and user experience
- Knowledge update velocity
- Business KPIs such as faster support resolution, improved compliance outcomes, or lower operational overhead
Enterprises also rely on SME feedback and user satisfaction scores to validate RAG effectiveness over time.
6. Is fine-tuning still needed if we use RAG?
It depends. RAG dramatically reduces the need for fine-tuning because it provides domain grounding directly via retrieval. However, some advanced enterprise use cases benefit from lightweight fine-tuning or instruction tuning on top of a RAG pipeline — especially when dealing with highly specialized terminology or workflows. The most common pattern is RAG-first, fine-tuning-second, used strategically rather than by default.
7. How does RAG handle conflicting or outdated data sources?
RAG can be designed with re-ranking, source verification logic, or content prioritization strategies to avoid amplifying conflicting information. Enterprises typically assign trust scores or metadata tags (e.g., “latest policy”, “validated by compliance”) to control which documents appear in retrieval. With proper governance, outdated or unverified content can be flagged, filtered, or excluded from the retrieval layer entirely.
8. Can RAG support multimodal enterprise data (images, graphs, tables)?
Yes. Modern RAG architectures support multimodal retrieval where the system can fetch images, graphs, structured tables, or even diagnostic scans — and combine them with text-based context. This is increasingly valuable in industries like manufacturing, radiology, pharma R&D, and e-commerce. Multimodal RAG enhances reasoning by allowing the LLM to see beyond text-only input.
9. What skills or roles are required to build and maintain a RAG system?
Successful RAG programs typically involve:
- Data engineers (pipelines, ingestion, governance)
- ML engineers (retrieval design, embeddings, vector search)
- AI architects (LLM integration, orchestration, performance)
- Domain SMEs (validation, taxonomy development)
- Security and compliance leaders (access controls, governance policies)
Techment provides cross-functional teams that cover the full lifecycle, reducing the burden on internal IT and accelerating deployment timelines.
10. Why choose RAG over traditional enterprise search or chatbots?
Traditional search retrieves documents; traditional chatbots rely on static rules. RAG combines both worlds by understanding intent, retrieving precise information, and generating conversational, context-aware responses grounded in enterprise truth. This leads to higher accuracy, better user experience, and significantly improved trust — essential for modern AI-driven enterprises.
Further read The Anatomy of a Modern Data Quality Framework: Pillars, Roles & Tools Driving Reliable Enterprise Data – Techment