
What Is a Golden Dataset?
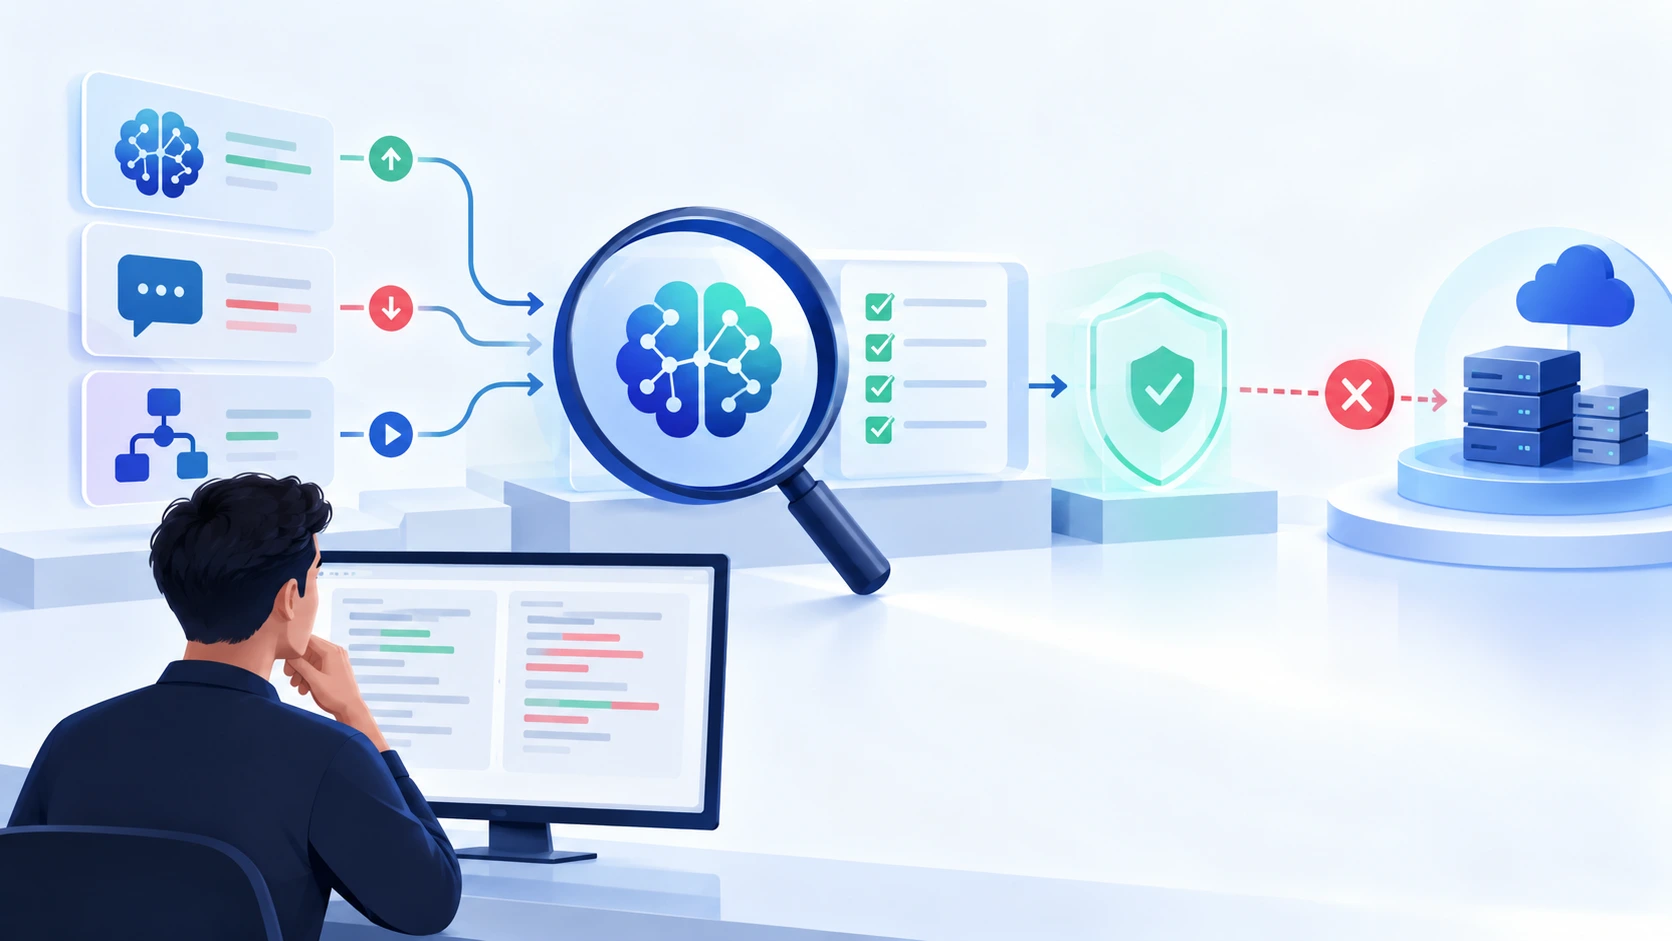
A golden dataset is a curated and expert-validated collection of inputs, expected outputs, evaluation criteria, and edge cases used as a trusted reference for evaluating AI systems. For GenAI applications, it provides a consistent baseline for measuring accuracy, relevance, safety, groundedness, compliance, and regression across model or application changes.
Unlike a conventional test dataset, a golden dataset represents the behaviors an organization considers correct, safe, and acceptable. It can be used for LLM evaluation, RAG validation, regression testing, hallucination detection, AI governance, and model comparison.
In simple terms, a golden dataset answers one critical question:
“What should the AI system do when it receives this input?”
By defining that expected behavior in advance, organizations can evaluate probabilistic AI systems against a consistent reference point.
Golden datasets for GenAI testing have become the foundation of trustworthy AI systems. As enterprises scale Large Language Models (LLMs) and Retrieval-Augmented Generation (RAG) applications, traditional testing methods fall short. Reliable AI benchmarks are now essential to ensure accuracy, safety, compliance, and consistent model behavior across versions.
TL;DR
- Golden datasets for Gen AI testing are ground-truth datasets used to evaluate GenAI performance and govern safe AI behavior.
- Building GenAI benchmarks requires domain alignment, data diversity, SME validation, and compliance review.
- Maintenance involves periodic updates, drift monitoring, and continuous automated evaluation.
- A well-governed golden dataset enables trustworthy, repeatable, and audit-ready GenAI testing.
- Best practices combine human expertise with metric-driven automated evaluation.
Learn more about how we help organizations embed AI-powered testing into their development lifecycle through our AI-testing services.
Golden Dataset vs Benchmark vs Test Dataset: What’s the Difference?
Golden datasets, generic test datasets, and public benchmarks are related but serve different purposes.
| Attribute | Golden Dataset | Generic Test Dataset | Public Benchmark |
|---|---|---|---|
| Primary purpose | Validate expected enterprise behavior | Test application functionality | Compare model performance |
| Ground truth | Expert-validated | May vary | Usually predefined |
| Enterprise-specific | High | Medium | Usually low |
| Compliance coverage | Can be embedded | Limited | Usually limited |
| Edge-case coverage | Deliberately designed | Variable | Depends on benchmark |
| Regression testing | Excellent | Good | Limited |
| Model comparison | Excellent | Moderate | Excellent |
| Production relevance | High when refreshed | Variable | Variable |
| Governance value | High | Moderate | Limited |
Key takeaway: A public benchmark can tell an enterprise how a model performs on standardized tasks. A golden dataset goes further by defining what correct, safe, relevant, and compliant behavior means for a specific enterprise use case.
Why Golden Datasets for GenAI Testing Matters?
Golden datasets for Gen AI testing are more than just a collection of examples — they are the benchmarking backbone of GenAI evaluation. Golden datasets bring scientific rigor to systems that are inherently non-deterministic. Their importance spans multiple dimensions: In a rapidly evolving landscape where models generate varied and often unpredictable outputs, golden datasets establish the foundation for trust, consistency, and accountability in testing. Their significance can be understood through the following dimensions:
Define the Ground Truth for Consistent Evaluation
GenAI outputs can vary even when inputs remain constant. Golden datasets counter this variability by establishing:
- Golden datasets for Gen AI testing act as the “single source of truth” that establishes reference outputs against which model predictions are measured. Canonical expert-reviewed responses serving as the “official knowledge.”
- They ensure repeatable and consistent evaluation cycles across different teams, timeframes, or iterations of the same model.
Without the Golden datasets for Gen AI testing, organizations risk subjective judgments and inconsistent testing outcomes.
Enable Apples-to-Apples Comparison Across Models
A shared benchmark allows organizations to compare Multiple LLM vendors and successive model versions to eliminate guesswork and ensures procurement, engineering, and risk teams evaluate models objectively.
- By providing a shared evaluation baseline, golden datasets for Gen AI testing allow fair comparisons of models trained under different conditions or from different vendors.
- This comparative framework is essential for enterprises assessing multiple Large Language Models (LLMs) before making investment decisions.
- Golden datasets for Gen AI testing also helps benchmark in-house models against industry standards.
Reduce Subjectivity in Model Evaluation
Tasks like summarization or advisory guidance often rely on subjective interpretation. Golden datasets for Gen AI testing eliminate ambiguity by pairing inputs with domain-approved canonical answers, ensuring consistency in scoring—whether automated or human-reviewed.
- Evaluating GenAI outputs often involves subjective judgment — especially tasks like summarization, creativity, or translation.
- Golden datasets mitigate this subjectivity by anchoring evaluation in objective, curated data, minimizing the influence of personal bias or inconsistent reviewer perspectives.
Support Compliance and Regulatory Audits
Golden datasets provide traceability of expert, legal, and compliance approval, audit logs for regulated sectors (finance, healthcare, insurance) and documentation of policies and safety constraints. This aligns with emerging Responsible AI frameworks such as the EU AI Act and ISO/IEC AI governance standards.
- As governments and industries move toward AI governance and ethical frameworks, golden datasets provide the documented evidence trail needed for audits.
- They demonstrate due diligence in testing practices and help organizations align with global regulatory standards (e.g., EU AI Act, ISO/IEC AI guidelines).
Increase Transparency for Stakeholders
Golden datasets for Gen Ai testing create explainability and trust for leaders to see quantifiable performance and risk data
- Transparent evaluation through golden datasets builds trust among stakeholders, including business leaders, regulators, and end-users.
- Golden datasets for Gen Ai testing not only validate the model’s reliability but also enhance adoption by showing that performance claims are backed by standardized evidence.
Accelerate Adoption and Integration
Compliance teams understand boundaries and refusal behavior, and engineering teams gain clarity on expected outcomes.
- By reducing ambiguity and risk, golden datasets streamline decision-making for enterprises looking to deploy GenAI solutions.
- Their use reassures stakeholders that models have undergone rigorous, unbiased, and repeatable testing.
In short: Golden datasets are indispensable for transforming GenAI testing from subjective assessment into a scientifically rigorous, auditable, and stakeholder-friendly process. They bridge the gap between innovation and trust, ensuring GenAI systems are not only powerful but also dependable.
More recently, Gartner’s May 2026 research states that building an AI agent without the ability to evaluate it is “extremely high-risk” and recommends that organizations build organization-specific evaluation suites alongside their agent
Discover how we helped one of our clients save manual testing efforts, enabling redirection towards strategic planning in our latest case study.
What Should a Golden Dataset Contain?
A reliable golden dataset should contain more than prompts and expected answers.
| Component | Purpose |
| Input or prompt | Defines the scenario being evaluated |
| Expected output | Establishes the reference behavior |
| Evaluation rubric | Defines how quality should be scored |
| Domain context | Captures business-specific requirements |
| Risk category | Identifies safety or compliance importance |
| Edge-case flag | Identifies difficult or unusual scenarios |
| Source/reference | Supports factual grounding |
| Dataset version | Enables reproducible evaluation |
| SME/owner | Establishes accountability |
| Evaluation history | Tracks performance over time |
The exact structure depends on the GenAI use case, but every enterprise dataset should have clear ownership, evaluation criteria, version control, and a defined purpose.
Golden Dataset vs Random Sampling: Which Should Enterprises Use?
Golden datasets and random production samples serve different purposes.
| Factor | Golden Dataset | Random Production Sampling |
| Purpose | Controlled evaluation | Discover real-world behavior |
| Repeatability | High | Medium |
| Critical scenarios | Intentionally included | May be missed |
| Edge cases | Can be deliberately added | Depends on occurrence |
| Regression detection | Strong | Moderate |
| Production realism | Moderate to high | Very high |
| Best use | Release gates and benchmarking | Monitoring and emerging-failure discovery |
Best practice: Enterprises should use both. Golden datasets provide controlled regression testing, while production sampling exposes unexpected behaviors and new failure modes that may not yet exist in the benchmark.
Key Principles of Building Golden Datasets for GenAI Testing
1. Define Clear Evaluation Objectives
Golden datasets should align with your model’s use case—be it summarization, sentiment analysis, or RAG-based knowledge retrieval.
- Example: For a healthcare chatbot, golden datasets must capture medical terminology, patient FAQs, and compliance-sensitive scenarios.
2. Balance Data Diversity
A reliable GenAI benchmark accounts for:
- Linguistic diversity (different dialects, tones, and cultural references).
- Content diversity (structured vs unstructured data).
- Contextual diversity (edge cases, adversarial prompts).
3. Maintain Human-in-the-Loop Validation
Human experts remain critical in labeling and verifying GenAI evaluation datasets. For instance, medical data labeling requires domain experts, not crowd workers.
4. Ensure Data Governance & Compliance
- Follow GDPR, HIPAA, and region-specific AI regulations.
- Mask or anonymize sensitive data before inclusion.
Learn how Techment’s Test Automation Implementation service ensures compliance.
Steps to Building GenAI Benchmarks
Step 1: Dataset Collection
Sources include:
- Historical user interactions.
- Domain-specific corpora.
- Public datasets (e.g., HuggingFace).
Step 2: Data Cleaning & Normalization
- Remove duplicates.
- Normalize formats (JSON, CSV, structured logs).
- Ensure consistent labeling conventions.
Step 3: Annotation & Labeling
- Use expert annotators.
- Implement double-blind labeling.
- Leverage annotation platforms with quality checks.
Step 4: Benchmark Design
- Define metrics: accuracy, BLEU, ROUGE, F1, factual correctness.
- Establish baselines (e.g., GPT-3.5 vs GPT-4 performance).
Step 5: Validation & Testing
- Pilot with a subset of models.
- Iterate based on errors and coverage gaps.
Read in detail on how by leveraging modern reporting tools, enterprises can drive both quality and speed at scale in our latest blog.
What Metrics Should You Use to Evaluate a Golden Dataset?
Different GenAI applications require different evaluation metrics.
| Metric | What It Measures | Best Used For |
| Accuracy | Correctness of the response | QA and factual tasks |
| Relevance | Whether the response addresses the query | AI assistants |
| Faithfulness | Whether output is supported by source context | RAG |
| Groundedness | Whether claims are supported by retrieved information | Enterprise RAG |
| Completeness | Whether important information is included | Knowledge assistants |
| Safety | Whether responses violate defined policies | High-risk AI |
| Bias/Fairness | Performance differences across groups | Sensitive applications |
| Consistency | Stability across repeated evaluations | Regression testing |
| Latency | Response time | Production applications |
| Cost | Evaluation/inference cost | Enterprise operations |
Maintaining Reliable GenAI Benchmarks
Golden datasets are not static — their relevance erodes over time, impacting the accuracy and fairness of GenAI evaluations. To ensure benchmarks remain reliable, organizations must address three major risks and adopt proactive strategies.
Why Golden Datasets Degrade Over Time
- Domain Drift
- Rapidly changing industries introduce new jargon, regulations, and user expectations.
- Outdated benchmarks fail to reflect real-world usage scenarios.
- Model Drift
- Large Language Models (LLMs) evolve through updates and retraining.
- Shifts in reasoning or response styles make past benchmarks less predictive of future performance.
- Bias Accumulation
- Repeated reliance on the same datasets can reinforce skewed or non-inclusive patterns.
- Without intervention, benchmarks may amplify inequities in sensitive domains like hiring, finance, or healthcare.
Strategies to Maintain Benchmark Reliability
Automated Monitoring Pipelines
- Continuously test new model outputs against golden datasets.
- Flag deviations early to prevent silent benchmark erosion.
- Integrate with CI/CD workflows to align model evaluation with production cycles.
Periodic Refresh
- Schedule monthly, quarterly or biannual dataset updates.
- Incorporate new user behaviors, emerging terminology, and regulatory requirements.
- Ensure test cases remain representative of evolving contexts.
Bias Audits
- Conduct fairness checks using quantitative bias metrics (e.g., disparate impact, equalized odds).
- Engage third-party evaluators for independent validation.
- Reduce the risk of reinforcing systemic biases in AI outcomes.
Version Control for Datasets
- Track dataset evolution with Git-like versioning systems.
- Enable reproducibility in GenAI testing by linking results to specific dataset versions.
- Provide transparency for audits, compliance, and cross-team collaboration.
Learn how Techment AI Testing Services future-proof testing strategies.
GenAI Testing Best Practices Using Golden Datasets
Combine Automated Metrics with Human Review
Automated evaluation tools are effective at measuring scale, consistency, and turnaround speed, but they often miss the subtlety required for subjective tasks such as summarization, translation, or content generation. Human validation ensures these nuanced aspects—like tone, context relevance, and factual accuracy—are properly assessed. The most effective GenAI testing strategies blend automation for efficiency with human-in-the-loop review for qualitative depth.
Align with Business KPIs
Golden dataset benchmarks should not exist in isolation; they must be tied directly to measurable business outcomes. For example: reducing hallucination rates in customer-facing chatbots, accelerating time-to-resolution in support workflows, or improving user satisfaction scores. When evaluation metrics are aligned with key performance indicators, teams can ensure that GenAI models are delivering tangible business value rather than just technical improvements.
Integrate into CI/CD Pipelines
Incorporating golden dataset validation into DevOps and CI/CD pipelines helps detect regressions early in the development lifecycle. By automating evaluation within release cycles, teams can catch accuracy drops, drift, or performance trade-offs before they impact production environments. This not only strengthens model reliability but also reduces the long-term cost of rework, ensuring that GenAI deployments remain robust and scalable.
Leverage AI Testing Frameworks
Dedicated AI testing frameworks and custom LLM evaluation harnesses play a pivotal role in streamlining benchmark execution. They enable consistent dataset validation, standardized reporting, and easier traceability across iterative model versions. By operationalizing golden dataset testing through structured frameworks, organizations can ensure repeatability, accelerate release cycles, and continuously improve model performance.
Learn more on how through our partnership with Tricentis, we deliver swift, cost-effective, and enterprise-grade test automation solutions.
Data & Stats Snapshot
- 60% of enterprises cite lack of reliable evaluation data as a barrier (Gartner).
- 70% of GenAI pilots fail to scale due to inadequate evaluation strategies (McKinsey).
- Companies adopting golden datasets report 30–40% reduction in hallucinations (Capgemini Research Institute).
- Continuous monitoring improves model reliability by 25% (Forrester).
Golden Dataset Checklist for Enterprise GenAI Testing
- Define the AI use case and evaluation objectives
- Identify critical business workflows
- Include common and edge-case scenarios
- Remove duplicates and low-quality examples
- Validate examples with subject-matter experts
- Define measurable evaluation criteria
- Include safety and compliance scenarios
- Version the dataset
- Integrate evaluation into CI/CD
- Monitor production failures
- Refresh the dataset periodically
- Track performance across model versions
Common Pitfalls & Practical Solutions
When building and maintaining reliable golden datasets for GenAI testing, teams often encounter recurring challenges that compromise accuracy, fairness, and long-term relevance. Below are some of the most common pitfalls — and practical ways to mitigate them.
Pitfall 1: Poor Data Quality
- Problem: Incomplete, inconsistent, or noisy datasets can skew testing outcomes and mask critical issues. This leads to unreliable benchmark scores and false confidence in system performance.
- Solution: Standardize defect categorization across teams and consistently clean historical logs before integrating them. Establish automated validation pipelines to detect anomalies early, ensuring that test datasets remain trustworthy and representative.
Pitfall 2: Overfitting Benchmarks
- Problem: Optimizing models solely against benchmark results often produces misleading outcomes. Such systems may excel in test environments but underperform in production with real-world variability.
- Solution: Complement benchmarks with golden datasets built from actual user scenarios and real-world traffic replay. This approach ensures that GenAI models are evaluated in conditions that mirror live environments, reducing the risk of brittle performance.
Pitfall 3: Ignoring Bias
- Problem: Golden datasets, if not carefully curated, may embed or amplify demographic, cultural, or contextual biases. This results in skewed outputs that can harm user trust and compliance.
- Solution: Conduct systematic fairness checks and diversify training and testing data sources. Proactively measure dataset representation across demographics and use debiasing techniques to minimize skew.
Pitfall 4: Static Datasets
- Problem: Benchmarks and golden datasets quickly lose relevance in dynamic domains where user needs, language patterns, or regulations evolve. Static datasets fail to capture emerging edge cases.
- Solution: Implement rolling updates and regular domain refresh cycles. Periodically inject new data from real-world interactions, ensuring that the test set remains aligned with evolving use cases and industry standards.
By proactively addressing these pitfalls, teams can maintain golden datasets that are not only accurate and unbiased but also resilient to change, enabling more reliable GenAI testing and deployment.
Explore our Test Automation Implementation Services for tailored enterprise adoption.
Executive Takeaway
Golden datasets should be treated as living enterprise evaluation assets—not static test files.
Their value comes from combining expert-validated ground truth, representative production scenarios, measurable evaluation criteria, version control, and continuous refresh.
When integrated with CI/CD, RAG evaluation, production monitoring, and AI governance, golden datasets provide enterprises with a repeatable way to detect AI regressions, compare models, identify emerging risks, and make GenAI performance measurable.
Conclusion
Golden datasets have become the backbone of reliable, safe, and enterprise-grade GenAI testing.
They transform subjective model evaluation into a governed, measurable, repeatable process rooted in expert knowledge and compliance oversight.
As organizations scale GenAI across customer service, healthcare, finance, insurance, and operations, one truth becomes clear:
There is no reliable AI without a well-governed golden dataset behind it.
Next Step: Contact Techment to implement AI-powered test automation and evaluation frameworks at scale.
FAQ Section
1. What are golden datasets in GenAI testing?
A golden dataset is a curated and expert-validated collection of inputs, expected outputs, evaluation criteria, and edge cases used as a trusted reference for evaluating GenAI systems. It helps measure accuracy, relevance, safety, compliance, and consistency.
2. Why are golden datasets important for LLM evaluation?
Golden datasets provide a consistent evaluation baseline for probabilistic AI systems. They reduce subjective testing, enable repeatable model comparisons, and help teams detect regressions when models, prompts, retrieval systems, or application logic change.
3. How is a golden dataset different from a benchmark?
A benchmark typically provides standardized tasks for comparing model performance. A golden dataset is usually customized to an organization’s business requirements and can include domain-specific behavior, compliance rules, expected outputs, and high-risk scenarios.
4. How do you create a golden dataset?
Create a golden dataset by defining evaluation objectives, collecting representative examples, cleaning and annotating data, defining expected outputs or evaluation rubrics, validating cases with subject-matter experts, and versioning the dataset for repeatable evaluation
5. How often should a golden dataset be updated?
There is no universal update interval. Update the dataset when models change, user behavior shifts, regulations change, new failure modes appear, or production data reveals coverage gaps. High-change systems may require continuous or monthly refreshes.
6. Can a golden dataset be used for RAG evaluation?
Yes. Golden datasets can evaluate whether a RAG system retrieves relevant evidence and generates answers that are accurate, complete, relevant, and grounded in that evidence.
7. What metrics should be used to evaluate GenAI systems?
Common metrics include accuracy, relevance, faithfulness, groundedness, completeness, safety, consistency, bias or fairness, latency, and cost. The appropriate metrics depend on the application’s business objectives and risk profile.